Category: Blog

Your blog category

  • Artificial Intelligence Integration Services: 2026 Guide

    Artificial Intelligence Integration Services: 2026 Guide


    TL;DR:

    • AI integration services embed AI into business systems to automate data handling and decision-making processes. Successful projects use phased deployment, focus on robust validation controls, and prioritize vendor transparency on failure management. Proper knowledge transfer and governance are essential to prevent vendor lock-in and ensure operational resilience.

    Artificial Intelligence Integration Services are defined as the process of embedding AI capabilities directly into existing business systems to automate, classify, and interpret data at scale. For document-heavy organizations, this is the difference between manual bottlenecks and real-time decision-making. Only 39% of technology leaders are confident their AI investments will yield positive financial returns. That gap exists because most teams focus on the technology itself rather than the integration quality behind it. Organizations with mature, AI-ready data capabilities achieve 65% better business outcomes. That number makes the case for getting integration right from the start, not as an afterthought.

    What are Artificial Intelligence Integration Services?

    Artificial Intelligence Integration Services connect AI models, including machine learning integration pipelines, natural language processing engines, and computer vision systems, to the workflows your teams already use. The industry term for this discipline is intelligent system integration, and it covers everything from API connections to full-scale AI deployment services that replace manual document handling. The goal is not to install a new tool. The goal is to make your existing systems smarter without rebuilding them from scratch.
    Hands coding AI integration in private office

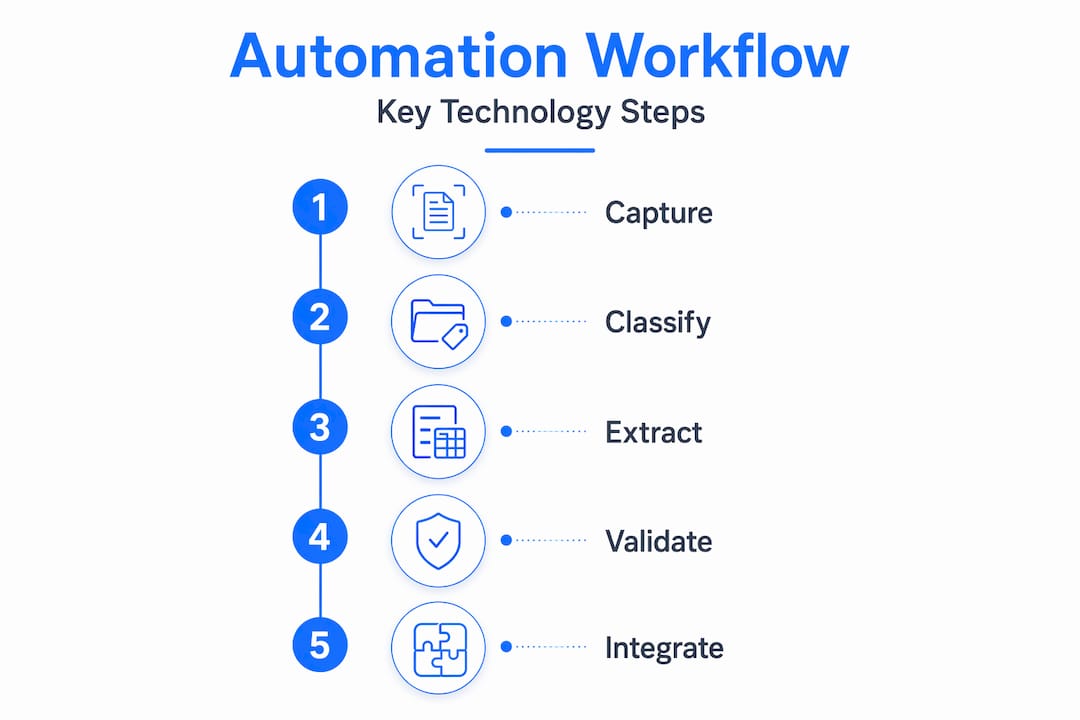
    For document workflows specifically, this means AI reads incoming files, extracts structured data, routes exceptions to human reviewers, and feeds clean records into your ERP or CRM. A manufacturer receiving hundreds of purchase orders daily does not need a bigger data entry team. They need an AI layer that reads each document, validates the data, and flags only the records that need a human decision. That is what mature AI integration solutions deliver.

    How do you evaluate AI service providers?

    Choosing the wrong AI service provider is expensive. Most teams make the mistake of evaluating vendors on team size, certifications, or the sophistication of their demo environment. Businesses most often fail by selecting partners based on buzzwords rather than production track record and a problem-first approach.

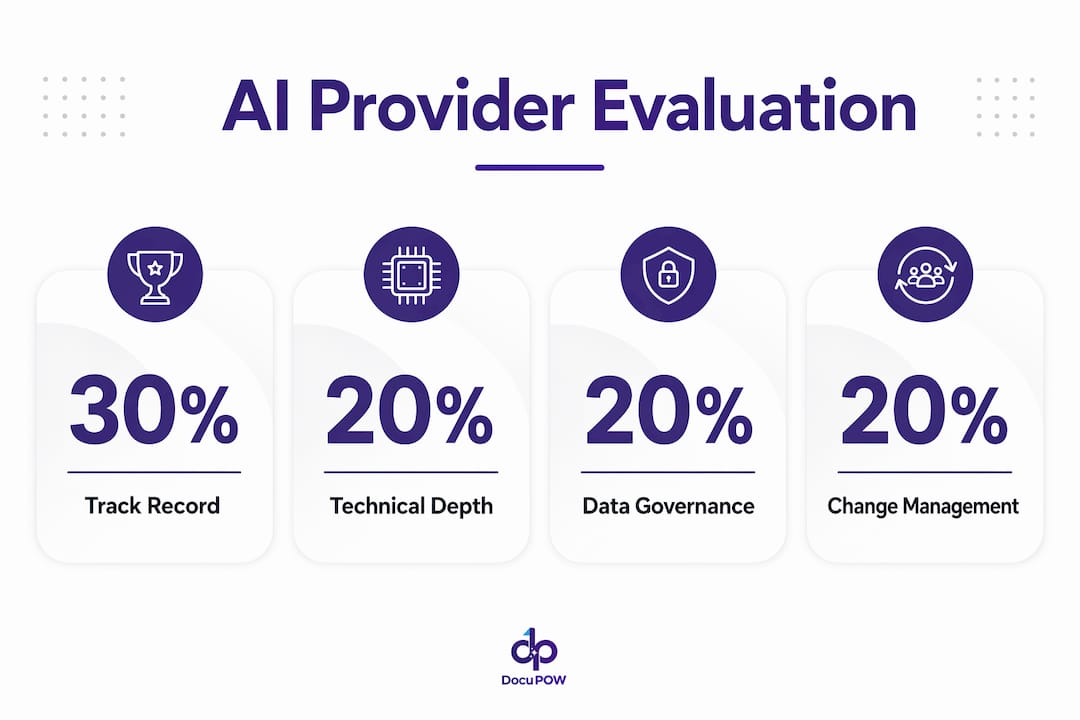
    A structured evaluation framework assigns weight to four factors:

    • Production track record (30%): Has the vendor deployed AI in production environments similar to yours? Ask for references from clients who went live, not just pilot customers. Any vendor scoring below 3 out of 5 on production maturity should be disqualified early.
    • Technical depth (20%): Can the team explain their model selection rationale, data pipeline architecture, and failure handling without defaulting to marketing language?
    • Data governance (20%): Does the vendor maintain audit trails, enforce access controls, and document data lineage? Governance is not optional for regulated industries.
    • Change management (20%): Does the vendor have a plan for training your team, managing resistance, and measuring adoption after go-live?

    Evaluation criteria weights place production track record at 30%, with technical depth, data governance, and change management each at 20%. That weighting reflects where real projects fail most often.

    Pro Tip: Ask every vendor candidate one specific question: “Describe a production failure you experienced and how you resolved it.” Vendors who give a concrete, honest answer demonstrate the operational maturity you need. Vendors who deflect or describe only successes are a red flag.
    Infographic of AI provider evaluation criteria

    What does a phased AI integration approach look like?

    Successful AI integration does not happen in a single deployment sprint. Phased integrations with short proof-of-concept pilots lasting 4–8 weeks, followed by structured legacy system integration, reduce long-term dependency risks significantly. That timeline is not arbitrary. It gives your team enough data to validate model performance before committing to a full rollout.

    A practical phased approach follows this sequence:

    1. Proof of concept (weeks 1–8): Run the AI model against a representative sample of your real documents. Measure extraction accuracy, exception rates, and processing speed. Set a minimum accuracy threshold before advancing.
    2. Legacy system integration (weeks 9–20): Connect the validated AI layer to your existing ERP, document management system, or workflow tool. Build the routing logic that sends exceptions to human reviewers.
    3. Parallel operation (weeks 21–28): Run AI and manual processes side by side. Compare outputs daily. This phase catches edge cases that the pilot missed.
    4. Full deployment and monitoring: Transition fully to AI-driven processing with live dashboards tracking accuracy, throughput, and error rates.

    Knowledge transfer is the step most vendors skip. Your team needs architecture documentation, operational runbooks, training sessions, and full source code ownership before the vendor relationship ends. Without these deliverables, you trade one dependency for another. Comprehensive knowledge transfer is what separates a successful integration from a long-term vendor lock-in situation.

    Pro Tip: Build a “day two” clause into your contract. This requires the vendor to provide a defined set of knowledge transfer deliverables, including runbooks and architecture diagrams, before final payment is released. It changes the incentive structure immediately.

    What are the technical risks in AI document processing?

    Document processing is not a single technical problem. Thoughtworks research identifies three distinct challenges: layout-aware text extraction, structural table parsing, and semantic interpretation. Each requires a different technical approach. Treating them as one problem leads to overengineered solutions that are fragile and expensive to maintain.

    The most dangerous risk in document AI is silent failure. Silent failure occurs when incorrect data passes through the system without triggering any error alert. A misread invoice total or a misclassified vendor code propagates through your ERP undetected. By the time someone notices, the downstream damage to compliance records or financial reports is already done.

    Validation and routing controls are the technical safeguards that prevent silent failure. These include:

    • Confidence thresholds: The AI flags any extraction below a set confidence score for human review rather than auto-approving it.
    • Schema validation: Every extracted record is checked against expected data types and value ranges before it enters your system.
    • Human-in-the-loop routing: Low-confidence or anomalous documents go to a reviewer queue, not directly to your database.
    • Audit trails: Every AI decision is logged with a timestamp, model version, and confidence score for traceability.

    Validation and human-in-the-loop review are mandatory controls, not optional enhancements. Teams that treat them as phase-two features consistently experience data quality problems within the first 90 days of production.

    Overengineering positional accuracy in layout extraction adds fragility without meaningful accuracy gains. A document AI system that breaks every time a vendor changes their invoice template is not production-ready. The better approach is training models on document intent rather than pixel-level position.

    How does AI integration benefit document workflows across industries?

    Mature AI integration solutions deliver measurable outcomes across manufacturing, real estate, construction, healthcare, and supply chain operations. Enterprises using mature AI integrations achieve improved automation in document workflows, which directly enhances decision-making speed and operational efficiency. The benefit is not theoretical. It shows up in processing time, error rates, and staff capacity.

    Specific document types that AI integration handles effectively include purchase orders, invoices, bills of lading, compliance certificates, contracts, and inspection reports. Each of these documents contains structured and unstructured data that traditional rule-based systems handle poorly. AI models trained on real document variation handle them accurately at scale.

    The business outcomes from AI-driven document automation include:

    • Faster invoice approval cycles, reducing days payable outstanding
    • Fewer manual data entry errors, which lowers rework costs and audit risk
    • Real-time visibility into document status across the supply chain
    • Compliance documentation that is complete, timestamped, and audit-ready without manual assembly
    • Staff redeployment from data entry to higher-value analysis and decision-making

    Operational agility is the outcome that surprises most teams. When your document processing runs on AI, you can absorb volume spikes, such as end-of-quarter purchase order surges, without adding headcount. That capacity flexibility has direct financial value. For real-world examples of AI document processing in manufacturing and logistics, the pattern is consistent: accuracy improves, cycle times drop, and teams shift from reactive firefighting to proactive planning.

    Compliance is another underrated benefit. Regulated industries require complete audit trails for every document decision. AI systems with proper governance built in generate those trails automatically. Manual processes rarely do.

    Key Takeaways

    Successful AI integration for document workflows requires production-proven vendors, phased implementation, and mandatory validation controls to prevent silent failures and long-term operational dependencies.

    Point Details
    Evaluate on production track record Weight vendor selection 30% on production maturity; disqualify any vendor below 3 out of 5.
    Use a phased rollout Run a 4–8 week proof of concept before committing to full legacy system integration.
    Treat document processing as three problems Layout extraction, table parsing, and interpretation each need a distinct technical approach.
    Mandate validation controls Confidence thresholds and human-in-the-loop routing are required to prevent silent data failures.
    Require knowledge transfer deliverables Architecture docs, runbooks, and source code ownership must be contractual, not optional.

    Why most AI integration projects underdeliver

    I have reviewed enough AI integration projects to recognize the pattern early. The vendor presents a polished demo. The procurement team is impressed by the interface. The contract gets signed. Then, six months into production, the team discovers that the model was never tested on their actual document formats, the vendor has no rollback plan, and the knowledge transfer “deliverables” amount to a slide deck.

    The teams that get this right share one habit: they evaluate vendors on how they handle failure, not how they describe success. Governed systems thinking means the vendor can show you their monitoring dashboards, explain their rollback procedure, and name the specific failure modes they have encountered in production. That level of transparency is rare. When you find it, it is worth paying for.

    The other mistake I see repeatedly is treating knowledge transfer as a courtesy rather than a contractual obligation. Your team needs to own the system after the vendor leaves. If you cannot explain how the model works, retrain it on new document types, or diagnose a drop in accuracy, you are not running an AI integration. You are renting one. That distinction matters enormously when the vendor raises prices or exits the market.

    Governance, monitoring, and rollback capabilities matter more than any individual feature. A system that can detect its own degradation and alert your team is worth more than one with a better extraction accuracy score on day one.

    — Sameer

    DocuPOW’s approach to document workflow AI

    DocuPOW builds AI integration specifically for document-heavy operations, using autonomous agents that read documents in context rather than matching against fixed templates. That architecture handles the document variation that breaks rule-based systems.
    https://docupow.ai

    Teams working with DocuPOW get a phased implementation approach, starting with a proof-of-concept phase on their actual document types, followed by structured integration into existing ERP and workflow systems. The platform includes real-time analytics and confidence-scored extraction, so your team always knows where the AI is certain and where it needs human review. For organizations ready to move from manual document handling to AI-driven document workflows, DocuPOW provides the operational support and governance structure that production deployments require. You can also review high-volume document processing best practices to prepare your team before the first integration phase begins.

    FAQ

    What are Artificial Intelligence Integration Services?

    Artificial Intelligence Integration Services embed AI models into existing business systems to automate data extraction, classification, and routing. For document workflows, this means AI reads incoming files and feeds structured data into your ERP or workflow tools without manual entry.

    How long does an AI integration project take?

    A proof-of-concept phase typically runs 4–8 weeks, followed by legacy system integration and parallel operation phases. Full production deployment for a document workflow integration commonly takes 6–9 months depending on system complexity.

    What is silent failure in document AI?

    Silent failure occurs when an AI system processes incorrect data without triggering an error alert, allowing bad records to propagate through downstream systems undetected. Confidence thresholds and human-in-the-loop routing controls are the primary safeguards against it.

    How do I evaluate AI service providers for document processing?

    Weight your evaluation 30% on production track record, 20% each on technical depth, data governance, and change management. Ask vendors to describe a specific production failure and how they resolved it before making any selection decision.

    What knowledge transfer should I require from an AI integration vendor?

    Require architecture documentation, operational runbooks, model training guides, and full source code ownership as contractual deliverables. These items should be tied to final payment to create the right incentive for the vendor to complete them properly.
  • Top 3 Ai Based Ocr Solution Alternatives 2026

    Top 3 Ai Based Ocr Solution Alternatives 2026

    Onboarding and automating complex, high volume document workflows without extensive manual setup remains difficult for enterprise teams. Most AI based OCR solutions demand template creation, repeated model training, or offer limited integration with core ERP and CRM systems. This comparison lets enterprise teams pick an alternative that minimizes manual setup and fits their integration needs without a trial-and-error cycle.

    Table of Contents

    DocuPOW

    https://docupow.ai

    At a Glance

    DocuPOW reports it can extract 100+ fields from any new document type without training data. Autonomous agents read, structure, and execute workflows on complex unstructured files while removing template setup. The platform combines conversational querying, a visual workflow builder, and encrypted role based controls, targeting enterprise volume and predictive credit based pricing.

    Core Features

    DocuPOW performs Zeroshot extraction to identify fields without labeled examples and supports PDFs, images, DOCX, and XLSX. The Infinity AI assistant provides conversational access to extracted data and supports human review where needed. DocuPOW Flow offers a visual workflow builder for multi step automation, and the platform accepts ingestion via email, API, SFTP, and web upload while keeping data encrypted and governed by role based permissions.

    Key Differentiator

    The platform pairs template free extraction with visual process orchestration and a conversational assistant to move document understanding directly into executable workflows. That design lets teams automate approvals, validations, and downstream system calls without separate model training for each document type. The focus shifts from repeated training work to mapping business processes around document data.

    Pros

    No template requirement shortens onboarding for new document types and reduces manual configuration across departments. Granular confidence scores and source transparency let reviewers trace each extracted value back to the original document. That traceability eases audits and supports human in the loop validation. Built in process orchestration and the conversational assistant let teams route documents into approval paths and export validated data to ERPs. Encrypted storage and role based permissions protect access and record audit trails.

    Cons

    • The platform’s complexity may require vendor led training for optimal setup.

    Who It’s For

    Large enterprise teams that handle complex, high volume document workflows will get the most value from DocuPOW. Teams in finance, legal, healthcare, or supply chain that need template free extraction and automated end to end processes fit well. Smaller teams with limited integration resources may find the initial setup heavier than simpler tools.

    Unique Value Proposition

    Zeroshot extraction that needs no labeled training lets organizations onboard new document types without long labeling projects. Removing template creation reduces time to live for automated workflows and lowers upfront configuration cost. Predictive credit based pricing helps align costs with variable document volumes and unusual invoice flows.

    Real World Use Case

    An accounts payable team automates invoice extraction, validation, and approval using DocuPOW. The system routes exceptions for human review and posts validated entries to the ERP. That configuration lowers manual data entry and improves financial visibility across suppliers.

    Pricing

    Pricing starts at $99/month for the Starter plan when billed annually. A free trial runs for seven days. Higher volume and enterprise plans are custom priced and the vendor uses predictive credit based pricing for usage.

    Website: https://docupow.ai

    super.AI

    https://super.ai

    At a Glance

    The vendor advertises over 94% accuracy using top AI models and human review. That figure highlights the product focus on measurable extraction accuracy for invoices, customs forms, and shipping documents. The platform targets rapid deployment without large training data sets.

    Core Features

    super.AI classifies and structures documents via direct upload or email monitoring, then extracts and validates key fields. The Agentic Workflow Builder lets teams compose workflows with no code while pre built connectors link outputs to ERPs and CRMs. The platform also uses models from OpenAI, Google, and Anthropic alongside human review to raise confidence in results.

    Key Differentiator

    The company states guaranteed accuracy through integrated human review paired with enterprise grade AI models and fast rollout. That approach shifts validation into the platform instead of leaving it to downstream checks. For enterprises, the mix of model options plus human review is the main operational distinction.

    Pros

    Immediate value arrives with small setup effort and minimal onboarding, which helps teams start processing documents quickly. Human review raises final result confidence and acts as a backstop on complex document layouts. Pre built enterprise connectors simplify integration with existing ERPs and analytics platforms, while deployment choices range from self service to enterprise scale.

    Cons

    • Pricing transparency can be limited for large scale enterprise plans, which complicates budgeting for high volume use.
    • The solution depends on third party AI models, and those models may perform differently across niche document types.
    • Some advanced workflows and integrations require technical expertise and custom configuration.

    When It May Not Fit

    If your team lacks engineering resources for custom connectors, this product can demand extra support. Organizations with strict, fixed budgets for massive document volumes may find enterprise pricing complex. If you need an out of the box solution with no customization at all, this product may feel heavier than simpler capture tools.

    Notable Integrations

    super.AI connects to SalesForce, SAP, IBM, Oracle, Snowflake, Active Directory, Microsoft Dynamics, and Zapier. Those integrations cover core ERP, CRM, identity, and data warehousing needs for enterprise workflows.

    Who It’s For

    Medium to large enterprises and growing teams that require high volume, accurate document processing tied into core systems. Buyers who want configurable workflows, enterprise controls, and options for vendor managed or self service deployment will get the most value.

    Real World Use Case

    The vendor says Bureau Veritas reduced processing time by 75% per project after adopting super.AI for data capture and validation. That reduction sped invoice reconciliation and cut manual review cycles for logistics paperwork.

    Pricing

    A free tier exists for basic use, and Growth starts at $140/month for 100k credits. Custom enterprise plans are available with volume pricing and service level agreements for large deployments.

    Website: https://super.ai

    Docxster

    https://docxster.com

    At a Glance

    Docxster reports integration with more than 100 applications, covering ERP, CRM, and document management systems. The platform lets business teams visually link forms, document processing, validations, and approvals without code. It targets mid to large enterprises that must coordinate document work across operations, finance, legal, HR, and IT.

    Core Features

    Docxster provides a visual workflow builder that connects modules such as forms, document reading, validations, data tables, and approvals in a single system. The product automates reading and data extraction from unstructured documents, supports multiple languages and formats, and includes governance tools like audit trails and approvals. Role based workflows and exception handling let teams add human review where needed.

    Key Differentiator

    The platform’s defining trait is its ability to wire all modules visually, so teams configure complex workflows without programming. That visual linking covers data capture, decision rules, and document generation in one canvas. For organizations that need multi-team processes to operate inside a single system, this visual approach reduces handoffs.

    Pros

    No code workflow design hands control to business teams and reduces dependency on IT. Deep integration support with major enterprise systems lets Docxster sit inside existing stacks and move documents and data between ERP, CRM, and accounting tools. Multi language, template free document reading handles messy files and multi party workflows with approvals and exception handling. The platform also includes enterprise security features such as encryption and audit trails to support compliance.

    Cons

    • Some features are marked “Coming soon,” which means parts of the platform are not yet complete.
    • Complex workflows still require training for administrators and reviewers despite the visual builder.
    • Heavy dependence on integrations creates limitations when a needed system is not supported.

    When It May Not Fit

    Docxster is not a good match for small businesses that need a lightweight single use tool. Organizations expecting a fully finished feature set immediately may be disappointed by modules listed as coming soon. Teams that lack core enterprise systems or cannot invest in integration work will see limited value. Projects that require simple point solutions rather than multi step workflows should look elsewhere.

    Notable Integrations

    Integrations include Microsoft 365, Google Workspace, SAP, Salesforce, HubSpot, Zoho, QuickBooks, and Cargowise. Those connectors support document routing, data sync, and approval handoffs across common enterprise applications.

    Who It’s For

    Mid to large enterprise organizations that require complex, multi step document workflows across departments will benefit most. Teams in logistics, finance, real estate, and legal that coordinate many stakeholders and approvals will find the visual builder useful. IT teams that already manage ERP or CRM systems gain value from the platform’s integration focus.

    Real World Use Case

    A logistics company automates shipment documentation and customs clearance by routing scanned paperwork through Docxster workflows. The system extracts data from invoices and certificates, runs validations, and triggers approvals from compliance teams. That setup reduces manual handoffs and shortens clearance timelines.

    Pricing

    Pricing is not publicly listed. Docxster appears to use enterprise customized pricing based on deployment size and selected modules. Contact the vendor for a quote and implementation details.

    Website: https://docxster.com

    Comparison of alternatives

    Organizations seeking advanced solutions for intelligent document processing have multiple platform options tailored to distinct needs. Below, we analyze three prominent contenders: DocuPOW, super.AI, and Docxster, identifying their unique strengths and ideal use cases.

    Automated data extraction performance

    DocuPOW excels with zero-shot field extraction, enabling document understanding without the need for pre-trained templates or datasets. This contrasts with super.AI, which builds its accuracy on pre-integrated AI models along with a human validation layer for maximum result confidence. Domxster, while also proficient in data extraction, emphasizes the processing of workflows through its visually driven system, appealing to departments requiring substantial customization.

    Workflow design and customization

    Among these platforms, Docxster leads in providing a no-code, visually driven workflow designer, allowing organizations to comprehensively link document processes to approvals and validations across departments. Its integration support extends to over 100 applications. In comparison, DocuPOW supports a visual workflow builder tailored for pre-structured, enterprise-grade workflows but may require vendor-led training for full utilization, while super.AI offers pre-built connectors that prioritize rapid deployments.

    Best fit

    • Enterprises handling high-volume, template-free document integration find enormous value in DocuPOW’s zero-shot extraction.
    • Teams demanding confidence through human-reviewed AI processing can leverage super.AI for superior accuracy on intricate documents.
    • Inter-departmental coordination involving human validation through integrated workflows benefits from Docxster’s visual designer and vast software integrations.

    Our pick

    For organizations requiring the most from streamlined, template-free document processing, DocuPOW emerges as the recommended choice. Its zero-shot extraction reduces onboarding times, and its predictive pricing model ensures costs stay aligned with usage variability. However, teams prioritizing extensive workflow customization or AI model variety might find Docxster or super.AI better align with their objectives.

    Large enterprises seeking an advanced AI-driven OCR solution can compare these three platforms based on their capabilities and target applications.

    Product Core Feature Key Differentiator Best For Pricing Notable Limitation
    DocuPOW Zeroshot extraction for diverse formats Template-free workflow orchestration Large enterprises with complex document workflows Starts at $99/month May require training for initial setup
    super.AI Human review and top AI models Guaranteed accuracy with human validation Medium to large enterprises Starts at $140/month Complex enterprise pricing structure
    Docxster No-code visual workflow design Integration with 100+ enterprise systems Mid to large enterprises needing inter-departmental workflows Price not published Some features marked “Coming soon”

    Challenges in Choosing the Right Ai Based Ocr Solution for Your Enterprise

    Handling diverse document types and high-volume workflows without extensive training stands out as a key challenge for medium to large enterprises. Teams face hurdles like time-consuming template setup, limited integration options, and difficulties in routing documents through complex approval paths. These issues increase manual work and delay critical financial and operational decisions.

    DocuPOW tackles these pain points with its zero-shot extraction technology that requires no labeled training data. The platform’s autonomous agents read and process unstructured files, while its visual workflow builder and conversational AI assistant reduce configuration effort and speed up validations. Companies gain secure, role-based access with traceable audit trails to improve compliance and data accuracy.

    Gain deeper insights from the AI Archives, learn about practical applications in the DocuPow Archives, and see how DocuPOW reshapes document workflows at https://docupow.ai.

    https://docupow.ai

    Make your document processing more efficient with DocuPOW. Visit our site to see how you can automate invoice extraction, validations, and approvals without long training projects and reduce manual errors today.

    FAQ

    How does DocuPOW’s Zeroshot extraction feature work?

    DocuPOW uses Zeroshot extraction to identify fields from new document types without the need for labeled examples. This capability allows teams to extract over 100 fields from PDFs, images, DOCX, and XLSX files without lengthy preparation. Users can expect quick onboarding for various document types without the traditional setup hassle.

    What is the difference between DocuPOW and super.AI?

    super.AI guarantees over 94% accuracy through integrated human review alongside advanced AI models, making it effective for documents like invoices and customs forms. DocuPOW’s strength lies in its template-free extraction and visual process orchestration, which may be more suited for teams needing to automate complex workflows. Consider your team’s specific needs when selecting between the two platforms.

    Can I use DocuPOW for multi-step automation?

    DocuPOW offers a visual workflow builder called DocuPOW Flow, which supports multi-step automation of document-related processes. This feature simplifies workflows by allowing teams to automate tasks such as approvals and validations directly within the platform. Teams should expect a streamlined experience in managing complex document workflows.

    Does DocuPOW provide role-based permissions for document access?

    Yes, DocuPOW ensures data security through encrypted storage and role-based permissions. This allows organizations to control who can access and process sensitive documents, which is crucial for compliance and audit trails. Teams can confidently implement document solutions while maintaining strict access controls.

    What pricing options are available for DocuPOW?

    DocuPOW’s pricing starts at $99 per month for the Starter plan when billed annually. There is also a free trial available for seven days, allowing teams to evaluate the platform before committing to a subscription. Higher volume and enterprise plans are custom priced, aligning costs with usage needs.

  • Cloud Analytics Services: A 2026 Guide for Decision-Makers

    Cloud Analytics Services: A 2026 Guide for Decision-Makers


    TL;DR:

    • Cloud analytics services are cloud-hosted platforms that process data to provide scaled business insights and real-time analysis. Effective deployment depends on robust architecture, semantic layers, data governance, and cost discipline from the start. They are especially valuable for industries with high-volume, time-sensitive data like retail, finance, healthcare, and manufacturing.

    Cloud analytics services are defined as cloud-hosted platforms that ingest, store, transform, and serve data to produce business intelligence at scale. The industry term for this discipline is “cloud-based analytics,” though “cloud analytics services” is the phrase most decision-makers search when evaluating vendors and architectures. Organizations that adopt these platforms replace fixed server infrastructure with consumption-based models, gaining the ability to process fragmented data sources, run AI-driven anomaly detection, and deliver real-time insights across global teams. Data governance frameworks, FinOps cost disciplines, and semantic layers are the three pillars that separate successful deployments from expensive failures.

    1. What are the core architectural layers of cloud analytics services?

    Modern cloud analytics architectures are built around four core layers: ingestion, storage, transformation, and serving. Each layer has a distinct job, and weakness in any one of them creates downstream problems that no dashboard can fix.

    Team discussing cloud analytics architecture layers

    Ingestion is where raw data enters the system. Sources include streaming feeds, API pulls, and scheduled batch imports from ERP systems, CRMs, IoT sensors, and document workflows. The ingestion layer must handle both high-frequency event streams and large periodic file loads without dropping records or introducing latency that distorts time-sensitive analysis.

    Storage sits beneath ingestion and holds data in three zones: raw, curated, and aggregated. Raw zones preserve original records with full lineage. Curated zones hold cleaned, validated datasets ready for analysis. Aggregated zones store pre-computed summaries that power fast dashboard queries. Lineage preservation at the storage layer is what makes audit trails and compliance reporting possible.

    Transformation converts raw records into analysis-ready datasets. This layer handles schema standardization, field enrichment, deduplication, and data quality checks. Without a disciplined transformation layer, teams end up with five different definitions of “monthly revenue” across five different reports.

    Serving is the output layer. It delivers data through dashboards, REST APIs, SQL notebooks, and AI-assisted interfaces. The serving layer is where business teams actually interact with data, so its design determines whether analysts can self-serve or must queue requests with engineering.

    Layer Primary Function Common Tools and Patterns
    Ingestion Collect data from all sources Streaming, batch imports, API connectors
    Storage Preserve raw and curated data Data lakes, warehouses, lineage tracking
    Transformation Clean, enrich, and standardize ETL pipelines, schema validation, quality checks
    Serving Deliver insights to end users Dashboards, APIs, AI interfaces, notebooks

    2. What key features distinguish effective cloud analytics services in 2026?

    The most common failure in cloud analytics is lifting legacy BI tools to the cloud without changing the underlying architecture. Inconsistent metrics and conflicting dashboards result when teams skip the semantic layer. A semantic layer creates a single, governed definition for every business metric, so “conversion rate” means the same thing in the marketing dashboard as it does in the finance report.

    Governed self-service is the feature that makes a semantic layer operational. It lets analysts query data independently without breaking shared metric definitions. Without it, every new report risks introducing a new version of the truth.

    Integrated FinOps is the second non-negotiable feature. Cost monitoring must be integrated from the start, with workloads tagged by environment, team, and business owner. Without tagging, spend reports show total cloud costs but cannot tell you which team or product line generated them. That makes cost control impossible.

    AI capabilities now include anomaly detection, causal analysis, and plain-English explanations of business impacts. Cloud analytics platforms enable AI-driven insights that translate raw signals into decisions without requiring a data scientist to interpret every alert. This is the feature that moves analytics from reporting to decision support.

    Data classification supports compliance and privacy requirements by tagging fields as public, internal, confidential, regulated, or restricted. Data classification models tie access rules directly to sensitivity labels, so regulated fields are automatically protected without manual policy enforcement.

    Pro Tip: Build your semantic layer before you build your first dashboard. Retrofitting metric definitions after teams have already built reports on inconsistent data takes three times as long and creates organizational friction that slows adoption.

    3. What are the common challenges when deploying cloud analytics services?

    Deployment challenges in cloud data analysis services cluster around four recurring problems: data quality, integration complexity, compliance gaps, and processing architecture mismatches.

    Data quality and lineage management are the most common sources of project failure. When source systems use inconsistent formats, missing values, or duplicate records, the transformation layer cannot produce reliable outputs. The fix is to define quality rules at ingestion, not transformation, so bad data is flagged before it enters the storage layer.

    Security and compliance governance must be designed into the architecture from day one. Data governance is essential to manage privacy, reduce risk, and meet regulatory requirements. Organizations that treat governance as a post-launch task consistently face audit failures and data breach exposure.

    Streaming versus batch processing creates stability problems when teams try to synchronize everything in real time. Synchronous processing of all data streams is a recognized pitfall. Best practice reserves synchronous pipelines for user-critical paths and uses asynchronous pipelines for the majority of data movement. This prevents cascading failures during peak load.

    Data ownership gaps produce the same result as governance gaps: no one is accountable when a metric is wrong. Assigning clear owners to each data domain, and encoding those owners in the semantic layer, is the operational fix. AI workflow governance follows the same principle: ownership must be explicit before automation can be trusted.

    Pro Tip: Run a data lineage audit before you migrate any existing reports to a new cloud analytics platform. Knowing where each field originates, and how it has been transformed, prevents you from inheriting legacy data quality problems in your new architecture.

    4. Which industries benefit most from cloud analytics services?

    The primary value of cloud analytics has shifted toward domain intelligence: automated, contextualized insights that translate raw data into business decisions. This shift benefits specific industries more than others because their operations generate high-volume, time-sensitive data that manual analysis cannot keep pace with.

    Retail and logistics use real-time operational intelligence to monitor inventory levels, detect supply chain disruptions, and adjust pricing within minutes of a demand signal. A retailer processing point-of-sale data across thousands of locations needs a cloud analytics platform that can ingest, transform, and serve insights faster than a nightly batch job allows.

    Finance and marketing benefit from AI-assisted domain intelligence. Fraud detection, customer lifetime value modeling, and campaign attribution all require the kind of causal analysis that modern cloud platforms now deliver through automated investigation pipelines. These teams no longer need to wait for a data scientist to build a custom model for each question.

    Regulated industries including healthcare and financial services use cloud analytics for compliance-driven reporting. Data classification and governance are the features that make cloud analytics viable in these sectors. Platforms that cannot enforce field-level access controls and audit trails cannot meet HIPAA, SOX, or GDPR requirements.

    Manufacturing and construction use cloud analytics to integrate fragmented document workflows with operational data. When purchase orders, invoices, and delivery records live in separate systems, cloud analytics platforms that connect those sources give operations teams a single view of project cost and progress.

    5. How to evaluate and choose the best cloud analytics services for your organization

    The evaluation criteria that matter most are architectural fit, governance support, cost model transparency, and AI capability depth. Generic feature checklists miss the decisions that actually determine whether a platform succeeds at scale.

    Architectural fit means the platform must match your existing data sources and scale requirements. An organization running high-volume document workflows needs a platform with strong batch ingestion and lineage tracking. An organization running real-time operations needs low-latency streaming pipelines. Most enterprises need both, which is why hybrid architectural approaches that balance asynchronous bulk processing with synchronous critical paths are the most practical choice.

    Governance support is the criterion most teams underweight during evaluation. A platform that cannot enforce a semantic layer, assign data ownership, or classify fields by sensitivity will create governance debt that compounds over time. Evaluate governance features as rigorously as you evaluate query performance.

    Cost model transparency separates platforms that align spend with business value from those that generate surprise invoices. Pay-as-you-go pricing models replace fixed hardware costs with consumption-based operational spend. That flexibility is only useful if the platform provides workload-level cost attribution so you can see exactly what each team or product is spending.

    AI capability depth determines whether the platform delivers domain intelligence or just faster reporting. Evaluate whether the AI layer can detect anomalies, explain causality in plain language, and trigger automated investigations. Platforms that offer only visualization with a machine learning add-on are not the same as platforms with native AI-powered insight generation.

    Pro Tip: Request a cost attribution demo before signing any contract. Ask the vendor to show you how workload tagging works and what a monthly FinOps report looks like. If they cannot show you field-level cost breakdowns, the platform will not support real cost discipline.

    Evaluation Criterion What to Look For
    Architectural fit Supports both streaming and batch; matches your data source types
    Governance support Semantic layer, data ownership assignment, field-level classification
    Cost model transparency Workload tagging, consumption-based billing, FinOps reporting
    AI capability depth Native anomaly detection, causal analysis, plain-language explanations
    Integration flexibility API connectors, document workflow support, enterprise system compatibility

    Key Takeaways

    Successful cloud analytics adoption requires a governed, four-layer architecture with FinOps cost discipline and a semantic layer embedded from day one, not added after the first dashboard goes live.

    Point Details
    Architecture is the foundation Build ingestion, storage, transformation, and serving layers before adding AI or dashboards.
    Semantic layers prevent metric chaos Define every business metric once, centrally, to stop conflicting reports across teams.
    FinOps must start at launch Tag workloads by owner and environment from day one to align cloud spend with business value.
    Governance is not optional Data classification and ownership assignment protect compliance and build organizational trust in data.
    AI delivers domain intelligence Use platforms with native anomaly detection and causal analysis to move from reporting to decisions.

    Why most cloud analytics projects fail before they scale

    I have watched organizations invest heavily in cloud analytics platforms and still end up with the same problem they started with: nobody trusts the numbers. The root cause is almost always the same. Teams migrate their existing reports to a new cloud environment and call it modernization. They do not rebuild the architecture. They do not install a semantic layer. They do not assign data owners. They just move the mess to a faster server.

    Effective cloud analytics modernization is architectural, not just a tooling swap. The organizations that get this right treat the semantic layer and FinOps discipline as infrastructure, not features. They define metric ownership before they write the first query. They tag every workload before they run the first pipeline. That discipline feels slow at the start. It pays back in months, not years, because teams stop arguing about which dashboard is correct and start making decisions.

    The other pattern I see consistently is teams underestimating the cost of streaming everything in real time. Real-time data is genuinely valuable for operational decisions. But synchronizing every data source in real time is expensive and fragile. The teams that build the most reliable platforms use asynchronous pipelines for the majority of their data and reserve synchronous processing for the paths where latency actually changes a business outcome. That distinction, made early, saves significant infrastructure cost and prevents the cascading failures that kill confidence in a new platform.

    My honest recommendation: treat your first 90 days on a new cloud analytics platform as an architecture sprint, not a reporting sprint. Get the governance, ownership, and cost tagging right before you build a single dashboard for a business stakeholder.

    — Sameer

    How DocuPOW connects document intelligence to cloud analytics

    Organizations running cloud analytics at scale still face one persistent gap: data trapped in documents never reaches the analytics layer. Purchase orders, invoices, contracts, and delivery records sit in static files while the analytics platform waits for structured inputs it never receives.

    https://docupow.ai

    DocuPOW closes that gap with AI-powered autonomous agents that extract, classify, and route document data directly into cloud analytics workflows, without rigid templates or manual entry. For teams in real estate and construction, DocuPOW transforms document-heavy operations into governed, analytics-ready data streams. The result is faster financial visibility and decision-making grounded in complete data. Explore how DocuPOW’s AI workflow automation integrates with your cloud analytics architecture to deliver the domain intelligence your operations need in 2026.

    FAQ

    What are cloud analytics services?

    Cloud analytics services are cloud-hosted platforms that collect, store, process, and deliver data insights at scale. They replace on-premise BI infrastructure with consumption-based models that support real-time analysis, AI-driven insights, and governed self-service.

    What is a semantic layer in cloud analytics?

    A semantic layer is a centralized definition of every business metric used across an organization’s analytics platform. It prevents conflicting dashboard results by ensuring that every team queries the same definition of each metric.

    Why is FinOps important for cloud analytics?

    FinOps aligns cloud analytics spend with business value by tagging workloads to specific teams, environments, and products. Without workload tagging, cost reports show total spend but cannot identify which operations are driving it.

    How does AI improve cloud analytics for businesses?

    AI in cloud analytics detects anomalies, identifies causal relationships, and delivers plain-language explanations of business impacts. This moves analytics from passive reporting to automated decision support without requiring a data scientist for every investigation.

    What industries benefit most from cloud-based analytics solutions?

    Retail, logistics, finance, healthcare, manufacturing, and construction benefit most. These sectors generate high-volume, time-sensitive data from fragmented sources that cloud analytics platforms can integrate, govern, and analyze faster than manual methods allow.

  • Top 6 Most Reliable Data Extraction Service Alternatives 2026

    Top 6 Most Reliable Data Extraction Service Alternatives 2026

    Processing high volumes of mixed business documents without losing accuracy or traceability is time consuming and prone to errors. Many data extraction services require manual template setup, complex rules, or hidden pricing that limits scale and transparency. This comparison measures accuracy, deployment choices, and integration features so teams can select the right service for their document workflow needs.

    Table of Contents

    DocuPOW

    https://docupow.ai

    At a Glance

    Zero shot extraction of 100+ fields from unseen document types works without training data. Autonomous AI agents read, understand, and route unstructured business documents into workflows and system updates. The platform removes template requirements and reduces manual data entry while preserving source citations for audit trails.

    Core Features

    DocuPOW uses natural language schema definitions and AI that adapts to varied document layouts and document types. The visual builder, DocuPOW Flow, orchestrates end to end document processes with human in the loop controls. Every extracted data point ties back to a verifiable source through Infinity, so teams retain traceable evidence for audits. The system also handles complex tables and nested line items so accounting fields map correctly.

    Key Differentiator

    The platform relies on advanced zero shot AI models that adapt instantly to new document formats without templates or retraining. That approach removes long training cycles and cuts the overhead of maintaining many extraction rules. For organizations processing mixed document types at scale, this changes how quickly data becomes system ready for ERPs and CRMs.

    Pros

    No templates or rigid rules are required, and the system adapts to irregular layouts while reporting confidence scores and source citations. The platform runs process automation that can validate totals, match purchase orders, and write results directly to ERPs via API or direct writes. Real time analytics and predictive insights help teams detect exceptions earlier and improve financial visibility and accuracy. Transparency with verifiable citations makes audits faster and reduces dispute resolution time.

    Cons

    • High initial setup complexity for some enterprise configurations and custom workflows.

    Notable Integrations

    • API
    • ERP systems via direct write or API
    • MCP compatible AI assistants such as Claude

    Who It’s For

    Enterprises and large teams that process complex unstructured documents at scale will benefit most. Global manufacturers, financial institutions, and logistics operators with heavy invoice and order flows gain faster financial visibility. Organizations that require audit trails and human in the loop oversight will find DocuPOW fits operational controls.

    Unique Value Proposition

    Autonomous agents run end to end document workflows with human in the loop controls. That capability turns unstructured files into system ready records and lets teams update ERPs and CRMs automatically. The result is faster financial visibility and earlier intervention on predicted exceptions, reducing manual reconciliation work.

    Real World Use Case

    A financial institution uses DocuPOW to extract thousands of supplier invoice fields and validate totals. The system matches invoices to purchase orders and writes reconciled records into the ERP while preserving audit citations. This reduced manual effort and lowered reconciliation errors while keeping traceable evidence for compliance.

    Pricing

    Starts at $99/month for 400 credits for the Starter tier, with higher tiers for professional and enterprise levels. Enterprise features such as custom SLAs and dedicated support require direct engagement and may affect pricing. Smaller teams should evaluate credit consumption against expected document volumes.

    Website: https://docupow.ai

    ABBYY FineReader Engine

    https://abbyy.com

    At a Glance

    The vendor advertises a pretrained recognition accuracy of 90%+. That claim is the most concrete technical metric ABBYY highlights for automated text capture and extraction.

    ABBYY pairs that recognition claim with enterprise tooling aimed at large-scale document projects. The marketing emphasizes uses across finance, healthcare, and manufacturing.

    Core Features

    ABBYY combines AI-powered document understanding with a low code platform that teams can configure without extensive developer work. The product set includes pretrained recognition models, tools for process mining and optimization, and connectors designed for enterprise deployment.

    These capabilities target capture from scanned images, PDFs, and unstructured documents while supporting many languages and file types. The platform scope ranges from single workflows to broad automation across back office systems.

    Key Differentiator

    ABBYY’s single most distinct claim is the pairing of high pretrained recognition accuracy with a low code deployment path. That combination aims to reduce the time between pilot and production for complex document projects.

    This accuracy claim sits behind product options that let organizations scale recognition and add process mining to analyze how documents move through operations.

    Pros

    ABBYY reports it is trusted by over 10,000 organizations, including Fortune 500 firms. That scale shows in vendor investments in enterprise features such as language support and broad document type coverage.

    The vendor reports 95% recognition accuracy out of the box, which vendors cite to shorten model training for common document classes. ABBYY also offers tools for process analysis so teams can find bottlenecks and tune capture rules.

    These strengths suit programs that need centralized management, language breadth, and enterprise integrations for downstream systems.

    Cons

    • Website pages report some 404 errors, which limits public access to detailed technical documentation and integration guides.
    • The product suite can be complex to deploy. Buyers often need dedicated professional services or internal implementation resources.
    • Third party reviewers advise careful product selection among ABBYY offerings to avoid buying a module that does not match a specific workflow.

    When It May Not Fit

    Small teams that need a lightweight plug and play capture tool will likely find ABBYY more than they need. Organizations without implementation support may struggle to configure advanced process mining and enterprise connectors. Buyers wanting full public documentation before engagement may be delayed by missing pages.

    Who It’s For

    Large enterprises seeking scalable, AI driven document processing and automation will get the most value. The product targets centralized IT teams, shared services centers, and operations groups managing high document volumes across multiple business units.

    Real World Use Case

    ABBYY cites customers such as FinTrU, Vinmar, and Carlsberg using the platform to automate regulatory compliance, invoice processing, and order management. Those deployments reduced manual data entry and supported faster handoff to ERP and compliance systems.

    Pricing

    Pricing is not published on the public site. The product is sold for enterprise projects and typically requires a sales conversation to get a quote and deployment options. Licensing models and support levels vary by deployment scope and scale.

    Website: https://abbyy.com

    UiPath

    https://uipath.com

    At a Glance

    Agentic AI that links human, robotic, and AI agents drives UiPath’s enterprise automation ambitions. The platform emphasizes orchestration across people, attended bots, and unattended robots to handle repeatable and decisioned work. That design targets large-scale rollouts with governance and control.

    Core Features

    UiPath offers tools to build, orchestrate, and govern automation workflows and to deploy both attended and unattended robots. The platform includes prebuilt solutions for industry and department use and connects to AI models, APIs, and third-party systems. End to end process automation and orchestration is supported with management and monitoring capabilities.

    Key Differentiator

    UiPath centers on agentic AI that coordinates human, robotic, and AI agents to run complex enterprise processes. That focus fits organizations aiming for broad automation coverage and strict governance. It differs from DocuPOW by prioritizing agent orchestration and enterprise governance rather than autonomous document-first extraction.

    Pros

    UiPath’s agentic approach lets teams combine human judgment with automated actors for tasks that require exceptions or approvals. The platform ships industry and department solution templates that reduce build time for common processes. Governance, security controls, and a developer community with certifications support large IT teams and center of excellence models. The vendor also wins recognition for document mining and analytics as part of its automation suite.

    Cons

    • Complexity can be high for teams without automation architects. Large deployments need planning and governance resources.
    • Enterprise features raise the learning curve. Smaller IT teams may struggle to run a full automation lifecycle.
    • Pricing specifics are not listed in the product brief. Smaller organizations should budget for potential cost and implementation effort.

    When It May Not Fit

    Organizations that need a light, single-purpose document extractor will likely find UiPath more than they need. Small businesses with limited automation staff may prefer simpler tools with lower setup overhead. Projects with tight budgets and no dedicated automation governance may face long timelines and higher total cost of ownership.

    Notable Integrations

    • Microsoft
    • SAP
    • Peak.ai
    • Coded agents
    • API automation

    Who It’s For

    Large enterprises and government agencies that need scalable, AI-enabled automation across multiple departments will match UiPath’s strengths. Teams that require governance, audit trails, and certification pathways will gain from the platform. Organizations planning broad process transformation and allocating dedicated automation resources will extract the most value.

    Real World Use Case

    UiPath’s marketing materials state that Omega Healthcare increased productivity by 100%, Johnson Controls saved $18M, and Uber achieved $22M in savings after automating processes. Those vendor-reported results illustrate how broad automation programs can cut manual effort and reduce cycle times when implemented at scale.

    Pricing

    Plans and pricing are listed on the vendor site. Specific tier details and cost examples are not provided in the product summary, so procurement should request enterprise quotes and total cost estimates for licensing, implementation, and governance services.

    Website: https://uipath.com

    Ephesoft

    https://ephesoft.com

    At a Glance

    Ephesoft reports a patented machine learning classification that adapts to diverse document types with high accuracy. The product supports cloud, on-premises, and hybrid deployment models to match enterprise constraints. Organizations use it for invoice processing, mailroom intake, and records digitization.

    Core Features

    Ephesoft captures data from both digital files and scanned paper, and it applies machine learning for document classification and extraction. The platform offers APIs and out of the box connectors so it integrates with ERP, RPA, BPM, and ECM systems. Deployment flexibility covers cloud, on premises, and hybrid setups for teams with varying compliance and infrastructure needs.

    Key Differentiator

    The platform centers on a patented machine learning based classification engine that learns from examples to improve extraction accuracy over time. That approach helps when documents arrive in many formats and templates. The vendor highlights industry recognition from third party reports for its intelligent document processing capabilities.

    Pros

    Ephesoft shows strong machine learning capabilities that reduce manual sorting and improve classification after initial training. Its flexible deployment choices let IT teams place processing where compliance or latency requirements demand. The product integrates with common enterprise tools and offers APIs for custom workflows, which helps connect capture to downstream ERP and automation systems.

    Cons

    • Limited public pricing: detailed costs are not listed and typically require a custom quote, which makes budget planning harder.

    • Complex initial setup: some customers report that installation and tuning need technical expertise or professional services for peak accuracy.

    • Migration friction: moving into the Kofax environment can require retraining and configuration changes for existing customers.

    When It May Not Fit

    If your team lacks technical staff or access to professional services, the initial setup could slow adoption. Organizations with small document volumes may find the implementation effort disproportionate to gains. If you need transparent list pricing for fast evaluation, Ephesoft will likely require contact with sales for a quote.

    Notable Integrations

    • ERP systems
    • RPA tools such as UiPath and Blue Prism
    • Content management systems like Alfresco and Nuxeo
    • Microsoft SharePoint and Power BI
    • APIs and connectors for custom integrations

    Who It’s For

    Enterprises and government agencies with high volume document intake will get the most from Ephesoft. Teams that must keep processing on premises for compliance will value the hybrid and on premises options. Organizations that already run RPA or ERP platforms will appreciate the connector set.

    Real World Use Case

    A large financial institution uses Ephesoft Transact to automate invoice and accounts payable processing. The system extracts vendor, date, and totals from varied invoice layouts and passes data into the ERP. That setup reduced manual keying and improved visibility into cash flow.

    Pricing

    Pricing is not explicitly listed. Costs are typically customized based on deployment model, volume, and desired modules. Expect to contact sales for a tailored quote and implementation estimate.

    Website: https://ephesoft.com

    Parseur

    https://parseur.com

    At a Glance

    Parseur’s marketing materials claim AI driven instant extraction that needs no training or templates and handles multiple layouts out of the box. The vendor advertises high uptime and auto scaling. The company also states GDPR and SOC 2 compliance and that HIPAA is in progress, and it claims connectors to thousands of apps.

    Core Features

    Parseur accepts documents via email, API, and direct upload, then runs parsing with Vision AI, Text AI, or template rules. Extracted fields are normalized and validated before real time exports to downstream systems. The product also includes fast OCR and connectors for common automation workflows.

    Key Differentiator

    The main distinction is the emphasis on instant, template free extraction for multi layout documents. That approach favors teams that must get reliable outputs the same day they begin. It fits buyers who prioritize rapid deployment over deep context aware document agents.

    Pros

    Setup requires no model training, so teams can parse common documents quickly and start routing data to other systems. Parseur supports invoices, receipts, bank statements, resumes, and varied PDF layouts, which suits companies with mixed document fleets. That uptime and scaling claim makes it practical for high volume ingestion, and the vendor’s compliance statements back a privacy focused posture. Native connectors and automation platform links reduce custom integration work.

    Cons

    • Pricing details and usage limits are not specified; the site says free to start but does not list tier limits or cost per document.
    • The marketing material does not detail how it handles highly complex layouts or deeply nested tables, so edge case performance is unclear.
    • No on premises deployment option is described, so organizations that require isolated infrastructure will need a different solution.

    When It May Not Fit

    If your workflows require on premises processing, Parseur is not a match because it operates as a cloud only solution. Organizations that need heavy customization of parsing logic or advanced context reasoning may find the product too focused on rapid, template free extraction. Teams expecting explicit published SLAs or transparent per document pricing will need more detail than the vendor provides.

    Notable Integrations

    Excel, Google Sheets, Zapier, Webhooks, Power Automate, Airtable, and Slack are listed as direct connectors. These integrations let you move parsed fields into spreadsheets, automation flows, or messaging channels without building custom middleware.

    Who It’s For

    Teams and businesses that need automated, scalable document extraction without investing in model training or heavy development will get the most value. Small to mid sized operations that process invoices, orders, resumes, or shipping documents will appreciate the quick setup. Enterprises that accept cloud based services and want connectors to existing automation platforms will also find this useful.

    Real World Use Case

    A finance team used Parseur to capture invoice line items from mixed supplier PDFs and emailed receipts. The company cut manual data entry hours and reduced posting errors by routing validated fields directly into accounts payable. That workflow sped approvals and kept parsed records tied to compliance controls.

    Pricing

    Parseur advertises a free starting tier followed by usage based pricing described as pay as you grow. Specific tier limits and per document rates are not listed publicly in the product copy.

    Website: https://parseur.com

    super.AI

    https://super.ai

    At a Glance

    super.AI reports Bureau Veritas cut processing time by 75% for data capture tasks. That customer result highlights handling of high-volume extraction across mixed document types. The platform pairs automated extraction with human review to reduce error rates in production workflows.

    Core Features

    The product can classify and structure documents automatically and extract key fields from invoices, bills, customs forms, and other formats. It validates extracted data in real time against enterprise systems and supports human in the loop review to catch edge cases. Pre-built connectors and APIs allow routing to ERP, CRM, and cloud systems while letting teams select different AI models per workflow.

    Key Differentiator

    The vendor says built in human in the loop review delivers guaranteed accuracy at scale without complex setup. That human review sits inside configurable workflows and elevates machine output before final routing. The combination reduces error volume while preserving automation throughput. Teams keep control of edge decisions through a review queue and policy controls.

    Pros

    According to the vendor, super.AI offers guaranteed service level agreements and human review to support accuracy requirements. It supports many document types and languages, which helps multinational operations. Deployment options include enterprise installations and a self service entry point, so teams can pilot before scaling. The product integrates with major enterprise systems and can run with multiple AI models to balance speed and precision.

    Cons

    • Setup complexity grows for very large enterprise deployments and may require dedicated technical resources.

    • Customizing workflows for highly specialized document types can be time consuming for internal teams.

    • The system depends on external AI models, and performance can vary with model selection.

    When It May Not Fit

    If you lack engineering capacity to build and maintain custom extractors, this product may require more internal work than a plug and play tool. If your documents are extremely novel or highly experimental, the vendor notes performance can vary on those file types. Small teams with low monthly volumes may find the enterprise options heavier than their needs.

    Notable Integrations

    • Salesforce
    • SAP
    • IBM
    • Oracle
    • SAS
    • ServiceNow
    • Snowflake
    • UiPath

    Who It’s For

    Large enterprises in logistics, finance, insurance, and supply chain will get the most from this product. Teams that must process high volumes of mixed-format documents and meet strict accuracy targets will benefit. Organizations that already operate ERP or data platforms will find the connector set useful.

    Real World Use Case

    Bureau Veritas saw a large time reduction in data capture tasks using the product, and that reduction demonstrates how automation plus human review can cut manual hours. Risk teams used the review queue to handle exceptions without stopping the main workflow. Finance groups routed validated fields directly into accounting systems to reduce reconciliation time.

    Pricing

    The vendor does not publish standard list pricing and appears to use custom enterprise contracts for large deployments. The vendor advertises a free self service option that includes 25,000 credits for testing and light use. Expect negotiated rates for volume processing and enterprise controls.

    Website: https://super.ai

    Comparison of alternatives

    Organizations processing unstructured document formats for data extraction will find compelling differences among the evaluated platforms. The following analysis explores how these platforms excel in unique dimensions and their use cases.

    Adaptive capability versus pretrained accuracy

    DocuPOW stands out by providing zero-shot AI models for handling undefined document formats, ensuring operational flexibility and reducing configuration overhead. Conversely, ABBYY FineReader Engine emphasizes high-accuracy OCR with pretrained models, beneficial for applications with repetitively standardized documents requiring recognition performance without further algorithm refinement. Enterprise-level clients focusing on adaptive versatility would benefit from DocuPOW’s flexibility, whereas predetermined accuracy under uniform workflows positions ABBYY favorably.

    Scalability and strategic implementation

    UiPath’s integration of attended and unattended robotic process automation caters to organizations implementing workflows requiring structured governance and multitiered agent orchestration. DocuPOW, while excelling in document-specific handling, does not prioritize multitier collaborations. Enterprises envisioning diverse operational strategies might prefer UiPath, which scales with tailored human-automated agent allocations allowing intricate governance models.

    Best fit

    • Enterprises seeking adaptive, autonomous capabilities for mixed-format document extraction and auditability should evaluate DocuPOW.
    • Teams prioritizing OCR with language support and process mining within centralized management will find ABBYY FineReader Engine beneficial.
    • Small to medium organizations requiring no-code deployment and straightforward document parsing favor Parseur.
    • Multinational corporations preferring human-in-the-loop capabilities for complex policy controls can consider super.AI.

    Our pick

    DocuPOW distinguishes itself through its advanced zero-shot extraction models, enabling dynamic adjustment to varied, unstructured documents without retraining. This makes it an solution for enterprises requiring adaptation. However, organizations requiring specialized centralized workflows with high initial pretrained accuracy,~ such as ABBYY FineReader Engine offers, might consider alternatives.

    When evaluating intelligent document processing tools, key features such as adaptability, deployment options, and pricing become crucial factors.

    | Product Name | Key Differentiator | Best For | Pricing | Notable Limitation |
    | DocuPOW | Zero-shot AI for mixed document types | Enterprises handling large-scale complex documents | Starts at $99/month | High initial setup complexity for enterprise configurations |
    | ABBYY FineReader Engine | High pretrained accuracy with low-code integration | Large organizations with multilingual needs | Price not published | Some online documentation missing |
    | UiPath | Agentic AI combining humans and bots | Governments and large-scale enterprises | Price not published | High complexity for small IT teams |
    | Ephesoft | Machine learning classification engine | Entities needing on-premises and hybrid deployments | Price not published | Complex setup requiring technical expertise |
    | Parseur | Rapid template-free extraction | Mid-sized businesses needing quick implementation | Pay-as-you-grow model | No on-premises deployment offered |
    | super.AI | Human review for guaranteed accuracy | Logistics and finance enterprises with strict accuracy targets | Free start with 25,000 credits | Setup complexity for large deployments |

    What Challenges Do Most Reliable Data Extraction Services Solve?

    Organizations handling large volumes of unstructured documents need a solution that adapts quickly without relying on rigid templates. DocuPOW meets this need with autonomous AI agents that read and extract data from multiple document types instantly. This approach reduces manual data entry, delivers real-time analytics, and preserves audit trails to improve financial clarity for global manufacturers and large teams.

    Explore how DocuPOW’s AI-driven workflows can accelerate your document processing and cut reconciliation errors. Learn more about our solution in the AI Archives – DocuPOW and related insights in the research Archives – DocuPOW.

    See the impact firsthand by visiting https://docupow.ai and start importing your documents to extract complex fields without templates.

    FAQ

    How does DocuPOW handle complex tables in document processing?

    DocuPOW efficiently processes complex tables and nested line items, ensuring that accounting fields map correctly. The system excels in extracting data from various document layouts without rigid templates. Organizations can expect accurate data extraction, which simplifies financial document management.

    What is the difference between DocuPOW and ABBYY FineReader Engine?

    ABBYY FineReader Engine excels with a pretrained recognition accuracy of over 90%, making it suitable for companies needing reliable text capture from various document types. In contrast, DocuPOW’s zero shot AI adaptation allows it to quickly respond to new document formats without lengthy training cycles, making it more efficient for businesses frequently handling diverse documents.

    Which platform is best for high-volume invoice processing and audit trails?

    DocuPOW is ideal for organizations requiring audit trails, as it preserves verifiable citations for compliance and oversight. The platform’s design targets enterprises involved in high-volume invoice processing while retaining necessary audit capabilities for transparency and accountability.

    Can I use super.AI for document workflows that involve human review?

    Yes, super.AI emphasizes human in the loop review for enhanced accuracy in document workflows. This feature allows users to ensure correct outputs before finalization, making it suitable for high-volume processing where quality assurance is crucial. DocuPOW, while also focusing on automated workflows, may be better for teams prioritizing rapid data extraction.

    How does pricing for DocuPOW compare to other services like Parseur?

    DocuPOW starts at $99 per month for 400 credits, providing a clear pricing tier for organizations. In contrast, Parseur offers a free starting tier but does not specify usage limits or costs per document, making budgeting more complex for potential users.

  • What Is End-to-End Document Automation?

    What Is End-to-End Document Automation?

    Most business managers assume document automation means converting paper to PDF or generating contracts from templates. That framing misses the point entirely. What is end-to-end document automation, really? It’s the complete, connected process of ingesting a document, extracting its data, validating it against business rules, and pushing that data into the systems your organization actually runs on — without a human touching it at every step. This guide breaks down how it works, why it matters for compliance and efficiency, and where most implementations go wrong.

    Table of Contents

    Key takeaways

    Point Details
    More than document creation End-to-end automation covers the full lifecycle from ingestion to system integration, not just generating files.
    AI drives accuracy at scale Technologies like OCR, NLP, and ML work together to extract and classify data from structured and unstructured documents.
    Compliance is built in Automated audit trails, standardized templates, and validation rules reduce regulatory risk across departments.
    Exception handling is non-negotiable Human-in-the-loop review for low-confidence cases keeps automation reliable without sacrificing accuracy.
    Integration depth determines ROI How well automation connects to your ERP, CRM, and other systems separates high-value deployments from expensive experiments.

    How end-to-end document automation actually works

    The phrase “document automation” gets used loosely, so let’s be precise. End-to-end automation integrates multiple departments and systems into one connected process, not just a single task like e-signature or template population. The workflow follows what the industry calls Intelligent Document Processing, or IDP.

    Here’s how a mature pipeline moves from raw document to business action:

    1. Ingest. Documents arrive from any source: email attachments, scanned paper, uploaded files, or API feeds. The system accepts PDFs, images, Word files, and more without requiring a specific format.

    2. Classify. The system identifies what kind of document it’s dealing with. An invoice looks different from a purchase order or a compliance certificate. IDP uses AI, ML, NLP, and OCR to scan, categorize, and organize data from physical and digital sources.

    3. Extract. Relevant fields are pulled from the document. Vendor name, invoice total, contract dates, policy numbers. This is where template-free AI extraction separates modern systems from legacy approaches.

    4. Validate. Extracted data is checked against business rules. Does the invoice amount match the purchase order? Is the contract date within the approved window? Low-confidence extractions get flagged for human review.

    5. Integrate. Clean, validated data flows directly into downstream systems: your ERP, CRM, accounting platform, or compliance database. No manual re-entry. No copy-paste errors.

    The technology stack behind the workflow

    Combining OCR with AI-driven classification is what makes it possible to handle structured and unstructured documents at scale. OCR converts image-based text into machine-readable characters. NLP interprets context, so the system understands that “remit to” and “pay to” both refer to the payee field. ML models improve over time as they process more documents, reducing error rates without manual retraining.

    Infographic for automation workflow technology steps

    One distinction worth knowing: IDP is the AI-powered subset of document automation. Automated Document Processing (ADP) often refers to older, rules-based systems that rely on fixed templates. End-to-end automation at the enterprise level typically combines both, with AI handling the extraction and classification while business rules govern validation and routing.

    Pro Tip: Before evaluating any platform, map out every system your documents need to touch after processing. The integration layer, not the extraction engine, is where most projects stall.

    The real business benefits of document automation

    Analyst archiving folder, graph on laptop

    Speed is the benefit most managers cite first, and it’s real. Turnaround times drop from hours to minutes when validation and data entry are automated. But the more durable benefits are accuracy and compliance, and those deserve more attention than they usually get.

    Here’s what organizations consistently report after deploying complete document automation solutions:

    • Fewer errors entering downstream systems. Validated, standardized data flows mean your ERP or accounting platform receives clean inputs. Manual re-entry is where most data corruption happens.

    • Audit trails without extra work. Every document, extraction, validation decision, and exception review is logged automatically. When a regulator asks for documentation of your approval process, you pull a report instead of reconstructing a paper trail.

    • Compliance enforcement at the source. Document automation enforces approved templates and standardized clauses, reducing the risk that a contract goes out with outdated terms or a missing clause.

    • Labor reallocation, not just labor reduction. Automation reduces manual busywork, freeing staff to handle judgment-intensive tasks that actually require human thinking.

    • Cross-departmental consistency. Finance, legal, HR, and operations all working from the same validated data eliminates the version conflicts that slow decisions.

    The cost savings from reduced physical storage and manual processing are measurable, but the harder-to-quantify benefit is decision speed. When your procurement team can see validated invoice data in the ERP within minutes of receipt rather than days, purchasing decisions and cash flow management both improve.

    Implementation challenges you need to anticipate

    Here’s where most document automation projects underdeliver. The technology works. The integration and governance around it often don’t.

    • Legacy system integration is the hardest part. Most enterprises run ERP or CRM platforms that weren’t built with API-first connectivity in mind. Getting clean data into those systems requires custom connectors, field mapping, and ongoing maintenance.

    • Workflow orchestration is more complex than it looks. Enterprise-grade automation requires event-driven triggers, queues, workflow states, confidence scoring, and human-in-the-loop exception management to function reliably. A simple extraction tool doesn’t give you any of that.

    • Data quality depends on input quality. Blurry scans, inconsistent document formats, and missing fields all degrade extraction accuracy. Garbage in, garbage out still applies.

    • Template dependence limits scalability. Systems built on rigid templates break when a vendor sends a slightly different invoice layout. Template-free extraction using AI handles document variation without manual reconfiguration.

    • Change management is underestimated. Staff who’ve built workflows around manual review need training, clear exception protocols, and confidence that the system flags what it’s uncertain about.

    Pro Tip: Start with a single high-volume, high-pain document type, such as vendor invoices or new hire onboarding packets. Prove the ROI there before expanding. Trying to automate everything at once is how projects lose executive support.

    Business rules and exception handling are not optional add-ons. They’re what separate a proof-of-concept from production-grade automation. Any vendor that can’t clearly explain how their system handles low-confidence extractions should raise a flag.

    Where document automation delivers across industries

    The applications span every department that touches documents, which is every department.

    Finance and procurement

    Invoice processing is the most common starting point, and for good reason. The volume is high, the format variation is significant, and the cost of errors flows directly to the bottom line. Automation handles three-way matching between purchase orders, invoices, and receipts, then routes exceptions for human review before pushing approved data to the ERP. For supply chain operations, this means faster payment cycles and better supplier relationships.

    Document automation covers the full contract lifecycle, from drafting through approval routing, version tracking, and compliance enforcement. Legal teams using automation report fewer redline cycles and faster time-to-signature. The audit trail is built in, which matters during disputes or regulatory reviews.

    Insurance and financial services

    Insurance document workflows involve high document volumes, strict regulatory requirements, and significant variation in form types. Automation extracts policy data, validates coverage terms, and routes claims documents without manual sorting. For fintech and banking, the same approach applies to loan applications, KYC documents, and compliance filings.

    Manufacturing and logistics

    Global manufacturers deal with bills of lading, quality certificates, customs documents, and supplier invoices across multiple languages and formats. Manufacturing document automation connects these documents directly to ERP systems, giving operations teams real-time visibility into supply chain status. For logistics providers, automated processing of shipping documents reduces clearance delays and billing errors.

    The table below shows how automation maps to specific use cases across departments:

    Department Document type Automation benefit
    Finance Vendor invoices Three-way match, ERP integration, error reduction
    Legal Contracts Lifecycle tracking, clause enforcement, audit trail
    HR Onboarding packets Data extraction, system population, compliance logging
    Operations Purchase orders Approval routing, validation, procurement system sync
    Logistics Shipping documents Real-time status updates, billing accuracy, customs prep

    Emerging trends worth watching include AI orchestration layers that coordinate multiple specialized models for different document types, and zero-shot learning approaches that handle document types the system has never seen before without retraining.

    My take: most organizations are solving the wrong problem

    I’ve watched organizations spend months selecting a document automation platform and then spend years fighting their own implementation. The pattern is consistent. They focus on the extraction engine and ignore the orchestration layer. They buy a tool that produces clean data extractions and then discover there’s no reliable way to route exceptions, track workflow states, or integrate with the five systems that actually need that data.

    The other mistake I see constantly is treating automation as a cost-cutting exercise rather than a workflow transformation. When the goal is headcount reduction, the project gets scoped too narrowly. You automate one document type, save a few hours per week, and declare success. The real value comes when automation connects across departments, so a validated invoice automatically triggers a payment approval workflow, updates the vendor record in the CRM, and logs the transaction in the ERP without anyone touching it.

    Exception management is where I’d tell every decision-maker to spend disproportionate attention. How the system handles the 15% of documents that don’t process cleanly determines whether your team trusts it for the 85% that do. A system that silently fails on edge cases will erode confidence faster than any other factor.

    The organizations I’ve seen get genuine ROI from end-to-end document automation share one trait: they treat it as a strategic capability, not a one-time deployment. They tune models, refine business rules, and expand integration depth over time. That ongoing investment is what separates a tool from a competitive advantage.

    — Vivek

    See what Docupow does differently

    https://docupow.ai

    Docupow is built for organizations that need more than a template-based extraction tool. Its AI-powered agents understand document context without rigid templates, which means it handles the variation in real-world document volumes that breaks rule-based systems. From operations and workflow automation to industry-specific deployments in insurance, logistics, real estate, and construction, Docupow connects document data directly to the business systems your teams rely on. The platform includes human-in-the-loop review, real-time analytics, and confidence scoring built into the workflow. If your organization is ready to move from manual processing to a production-grade automation pipeline, explore what Docupow can do for your specific document types and systems.

    FAQ

    What is end-to-end document automation?

    End-to-end document automation is the complete process of ingesting, classifying, extracting, validating, and integrating document data into business systems without manual handling at each step. It covers the full lifecycle from document receipt to data appearing in your ERP, CRM, or compliance platform.

    How does document automation differ from just using templates?

    Template-based systems break when document formats change, requiring manual reconfiguration. Modern IDP systems use AI to extract data from diverse document types without predefined templates, making them far more scalable.

    What technologies power document automation?

    Document automation combines OCR for text recognition, NLP for contextual understanding, and ML models that improve accuracy over time. Workflow orchestration tools manage routing, exception handling, and system integration.

    What are the biggest benefits of document automation?

    The core benefits include faster processing cycles, fewer data entry errors, built-in audit trails for compliance, and labor reallocation from manual tasks to judgment-intensive work. Compliance is enforced automatically through standardized templates and validation rules.

    Why do document automation projects fail?

    Most failures trace back to underestimating integration complexity, skipping workflow orchestration, or treating exception handling as an afterthought. Reliable enterprise automation requires event-driven triggers, confidence scoring, and human-in-the-loop review to function at production scale.