Author: tasnimkhan

  • Benefits of Automated Data Extraction in Manufacturing

    Benefits of Automated Data Extraction in Manufacturing

    Automated data extraction in manufacturing is the process of using intelligent tools to capture, process, and analyze data from documents and production systems without manual input. The benefits of automated data extraction in manufacturing span every layer of operations: lower labor costs, fewer errors, faster reporting, and real-time visibility that manual processes simply cannot match. Technologies like intelligent document processing (IDP) and AI-based automation are now the standard for manufacturers who need to move faster than their competitors. Platforms like DocuPOW and Improvado have made these capabilities accessible to manufacturers of every size.

    1. What are the core benefits of automated data extraction in manufacturing?

    Automated data extraction advantages go far beyond saving time on paperwork. The real payoff is a shift in how your entire operation makes decisions. When data flows automatically from purchase orders, quality reports, and inspection records into your systems, your team stops chasing numbers and starts acting on them.

    Automation makes data processing faster, more consistent, and scalable, supporting growing manufacturing data volumes without adding headcount. That means a plant running 10 production lines can handle the same data workload as one running 100, without hiring proportionally more staff.
    Hands typing at manufacturing workstation

    Pro Tip: Start your automation rollout with the document type that causes the most bottlenecks, typically purchase orders or quality inspection reports, before expanding to other workflows.

    2. Reduced labor costs and manual effort

    Manual data entry in manufacturing is expensive and slow. Workers spend hours keying data from paper-based purchase orders, supplier invoices, and compliance documents into ERP systems like SAP or Oracle. Implementing IDP in manufacturing can reduce document processing labor by 75–80% and cut reporting time by up to 80%.

    That is not a marginal efficiency gain. A plant that previously needed a five-person data entry team can redirect most of that capacity to higher-value work like supplier relationship management or quality analysis. The cost savings compound quickly across multi-site operations.

    3. Dramatically improved data accuracy

    Human error in data entry is not a rare event. It is a predictable, recurring cost. A miskeyed part number on a purchase order can trigger a wrong shipment, a production delay, and a compliance flag, all from one typo. IDP systems classify and extract documents with 95%+ accuracy, flag exceptions automatically, and route workflows for human review only when needed.

    That 95%+ threshold matters because it is the point where automated output becomes more reliable than manual input at scale. Manufacturers using IDP report fewer rework cycles and cleaner audit trails as a direct result.

    4. Faster processing and near real-time reporting

    Speed is a competitive advantage in manufacturing. When a supplier ships a non-conforming batch, you need to know within hours, not days. Automation in data analytics cuts reporting time by 80%, giving operations teams near real-time visibility into production and supply chain performance.

    That kind of speed changes how plant managers operate. Instead of waiting for end-of-week reports, they can act on live data from the floor. Decisions about reordering, rerouting, or escalating quality issues happen in the same shift the problem appears.

    5. Scalability without proportional cost increases

    Manual data processes break down as production grows. Adding a new product line, a new supplier, or a new facility means more documents, more data, and more staff to handle it. Manual processes break down under growing data and channel complexity, while automation enables scalable, reliable data flow without added manual workload.

    This is the scalability argument that resonates most with manufacturing decision-makers. You can double your document volume without doubling your back-office headcount. That ratio is the financial case for automation in a single sentence.

    6. Enhanced compliance and quality assurance

    Compliance in manufacturing is not optional. ISO standards, FDA regulations, and customer-specific quality requirements all demand documented, traceable data. Automated data extraction improves compliance by maintaining audit trails and validating data automatically, reducing compliance risks across the production lifecycle.

    Automated validation catches missing fields, out-of-range values, and format errors before they reach your ERP or quality management system. That means fewer failed audits, fewer corrective action reports, and less time spent reconstructing paper trails after the fact.

    7. Better decision-making through consistent data

    Decisions are only as good as the data behind them. When data comes from manual entry across multiple teams and shifts, inconsistencies creep in. Automated extraction produces a single, consistent data stream that every department can trust.

    Automation shifts teams from reactive manual processing to building data products that drive revenue and competitive agility. For manufacturing, that means production planners, procurement leads, and quality managers all work from the same numbers at the same time.

    How does intelligent document processing integrate with manufacturing automation?

    Intelligent document processing (IDP) is a technology layer that combines computer vision, natural language processing (NLP), and AI to read, classify, and extract data from documents automatically. In manufacturing, the document types that benefit most from IDP include purchase orders, goods receipt notes, quality inspection reports, certificates of conformance, and supplier invoices.

    Here is what IDP handles in a typical manufacturing workflow:

    • Document ingestion: Scans, PDFs, and digital files are pulled in automatically from email, ERP portals, or shared drives.
    • Classification: The system identifies the document type without manual tagging, using AI trained on manufacturing document formats.
    • Data extraction: Key fields like part numbers, quantities, dates, and supplier codes are pulled out and mapped to your data schema.
    • Exception handling: Documents that fall below the confidence threshold are flagged and routed to a human reviewer, not silently passed through.
    • Workflow routing: Extracted data flows directly into downstream systems like SAP, Oracle, or a quality management platform.

    IDP integrates with business process management (BPM) tools and robotic process automation (RPA) platforms to create end-to-end workflow automation. The result is a document pipeline that runs without manual intervention for the vast majority of transactions. For manufacturers processing thousands of documents per month, that pipeline is the difference between a two-day processing cycle and a two-hour one.

    Comparing automated data extraction tools for manufacturing

    Not every platform fits every manufacturer. The right choice depends on document complexity, integration requirements, and the scale of your operations.

    Platform Core strength Best fit Integration depth
    DocuPOW Template-free AI extraction with autonomous agents Global manufacturers with complex, varied documents ERP, BPM, and API-level connections
    Improvado API-level pipeline orchestration with schema adaptation Data teams managing multi-source pipelines Marketing and operational data stacks
    Aptimeta IDP Manufacturing-specific IDP with compliance focus Mid-size manufacturers with high document volume Quality management and ERP systems

    DocuPOW’s approach is worth noting specifically. Unlike template-based systems that require manual configuration for each document type, DocuPOW uses autonomous agents that understand document context. That means a new supplier invoice format does not require a new template build. The system adapts. For manufacturers dealing with hundreds of supplier formats, that flexibility is a significant operational advantage.

    Pro Tip: When evaluating platforms, ask vendors specifically how their system handles documents it has never seen before. Template-dependent tools will require manual setup every time a new format appears. Template-free systems like DocuPOW handle novel formats automatically.

    What operational challenges does automated data extraction solve?

    Manufacturing operations face a specific set of data problems that manual processes cannot fix at scale. Automated data collection addresses each one directly.

    • Manual entry errors: A single transposition error on a part number can trigger a wrong shipment, a production stoppage, or a failed audit. Automated extraction eliminates the human input that causes these errors.
    • Processing delays: Purchase orders and quality reports that sit in email inboxes for days create downstream delays in production scheduling and supplier payment. Automation processes these documents in minutes.
    • Scaling bottlenecks: As production volume grows, manual data teams become the constraint. Automation removes that ceiling entirely.
    • Lack of real-time visibility: Without automated data pipelines, plant managers rely on reports that are hours or days old. Automated extraction feeds live dashboards with current production and quality data.
    • Limited supplier visibility: Tracking supplier performance manually across dozens of vendors is impractical. Automated extraction from supplier documents creates a consistent performance record without extra staff.

    The role of data extraction in operations is no longer just administrative. It is a core operational function that directly affects throughput, quality, and cost.

    Key Takeaways

    Automated data extraction in manufacturing is the single most direct path from document-heavy operations to data-driven decision-making at scale.

    Point Details
    Labor reduction is measurable IDP cuts document processing labor by 75–80%, freeing staff for higher-value work.
    Accuracy exceeds manual input IDP systems extract data at 95%+ accuracy, reducing rework and compliance failures.
    Reporting speed transforms decisions Automated pipelines cut reporting time by 80%, enabling same-shift operational responses.
    Scalability removes growth ceilings Automation handles growing document volumes without proportional increases in headcount.
    Pipeline monitoring is non-negotiable Automated data flows require observability and alerts to catch silent errors before they compound.

    Why most manufacturers underestimate what automation actually changes

    The conversation about automation in manufacturing almost always starts with cost savings. That is the right place to start, but it is the wrong place to stop. What I have seen repeatedly is that manufacturers who implement automated data extraction for the labor savings end up discovering something more valuable: they finally have data they can trust.

    That shift matters more than the headcount reduction. When your quality manager, procurement lead, and plant director all pull from the same clean data source, the arguments about whose numbers are right disappear. Decisions get made faster because no one is waiting for someone else to reconcile a spreadsheet.

    The piece most implementation plans miss is observability. Automated data pipelines need monitoring for schema changes and failures. Without alerts, a silent pipeline error can corrupt data for weeks before anyone notices. I have seen manufacturers run flawed production reports for months because no one built a check into the pipeline. The technology is not the hard part. The discipline of treating your data pipeline like a production asset, with maintenance schedules, alerts, and ownership, is where most rollouts either succeed or quietly fail.

    Choose platforms that give you audit trails and exception logs, not just extraction outputs. DocuPOW’s approach of flagging low-confidence extractions for human review is the right model. Automation should make errors visible, not invisible.

    — Sameer

    How DocuPOW supports manufacturing data extraction
    https://docupow.ai

    DocuPOW is built specifically for the document complexity that global manufacturers deal with every day. Its AI-powered autonomous agents extract data from purchase orders, quality reports, inspection certificates, and supplier invoices without requiring templates or manual configuration. That means your team spends zero time building extraction rules for new document formats.

    Manufacturers using DocuPOW report faster financial close cycles, cleaner audit trails, and real-time visibility into supplier and production performance. The platform connects directly to ERP and BPM systems, so extracted data flows into your existing workflows without manual handoffs. Explore DocuPOW’s manufacturing automation solutions to see how the platform handles your specific document types and integration requirements. You can also review document process automation benefits for a deeper look at operational impact.

    FAQ

    What is automated data extraction in manufacturing?

    Automated data extraction in manufacturing is the use of AI and IDP tools to capture and process data from documents like purchase orders, invoices, and quality reports without manual input. It replaces manual data entry with automated pipelines that feed directly into ERP and quality management systems.

    How much labor can IDP reduce in manufacturing?

    IDP can reduce document processing labor by 75–80% in manufacturing environments. That reduction applies to tasks like keying purchase order data, processing supplier invoices, and compiling quality inspection records.

    What document types does automated extraction handle?

    Automated extraction handles purchase orders, supplier invoices, goods receipt notes, quality inspection reports, certificates of conformance, and shipping documents. IDP systems classify and extract these document types automatically, regardless of format or layout.

    How does automated data extraction improve compliance?

    Automated extraction maintains complete audit trails and validates data fields automatically before they enter downstream systems. That process reduces the risk of missing or incorrect data reaching compliance-sensitive records.

    What should manufacturers look for in an extraction platform?

    Manufacturers should prioritize template-free extraction, 95%+ accuracy, ERP integration, and built-in exception handling with human review routing. Observability features like pipeline monitoring and alerts are critical for catching errors before they affect production data.
  • Why IT Teams Manage Document Automation

    Why IT Teams Manage Document Automation

    Document automation is the technology-driven process of creating, routing, storing, and retrieving documents through predefined rules and AI-assisted workflows, rather than manual effort. IT teams manage document automation because it directly controls efficiency, compliance, and data integrity across the entire organization. Platforms like Microsoft 365 already give IT teams the ability to automate workflows and tag documents with metadata, co-edit in real time, and reduce project delays. The result is fewer errors, faster approvals, and a document environment that scales without adding headcount. Finance, accounting, legal, and operations all depend on the infrastructure IT builds and maintains.

    Why IT teams manage document automation for efficiency

    Document automation cuts the time IT teams spend on repetitive, low-value document tasks. Accounting firms using standardized document automation save 30–60 minutes per letter, and that compounds across hundreds of engagements annually. The same math applies to IT teams generating change requests, incident reports, system runbooks, and vendor contracts at scale.

    Automation handles the tasks that consume the most calendar time without producing strategic value. Document generation, approval routing, version control, and distribution can all run on rules-based triggers. When those tasks run automatically, IT staff shift their attention to architecture decisions, security reviews, and system improvements.

    Close-up of hands adjusting document workflow diagrams

    AI-driven intake portals illustrate the speed gain clearly. These systems cut onboarding time from days to hours by automating data extraction and document classification the moment a file enters the system. For IT teams managing vendor onboarding or employee provisioning, that compression in cycle time is operationally significant.

    Better documentation also reduces mean time to resolution. Solid documentation and automation improve MTTR, which is the time it takes to diagnose and fix a system failure. Shorter MTTR means less downtime and lower incident costs, both of which matter to IT leadership and the business units they support.

    • Document generation: Templates auto-populate from system data, eliminating manual drafting of recurring reports and tickets.
    • Approval routing: Workflows send documents to the right reviewer based on document type, value threshold, or department, without human intervention.
    • Version control: Every edit is tracked automatically, so IT teams can audit changes without digging through email chains.
    • Search and retrieval: Metadata tagging replaces folder hierarchies, making documents findable in seconds rather than minutes.

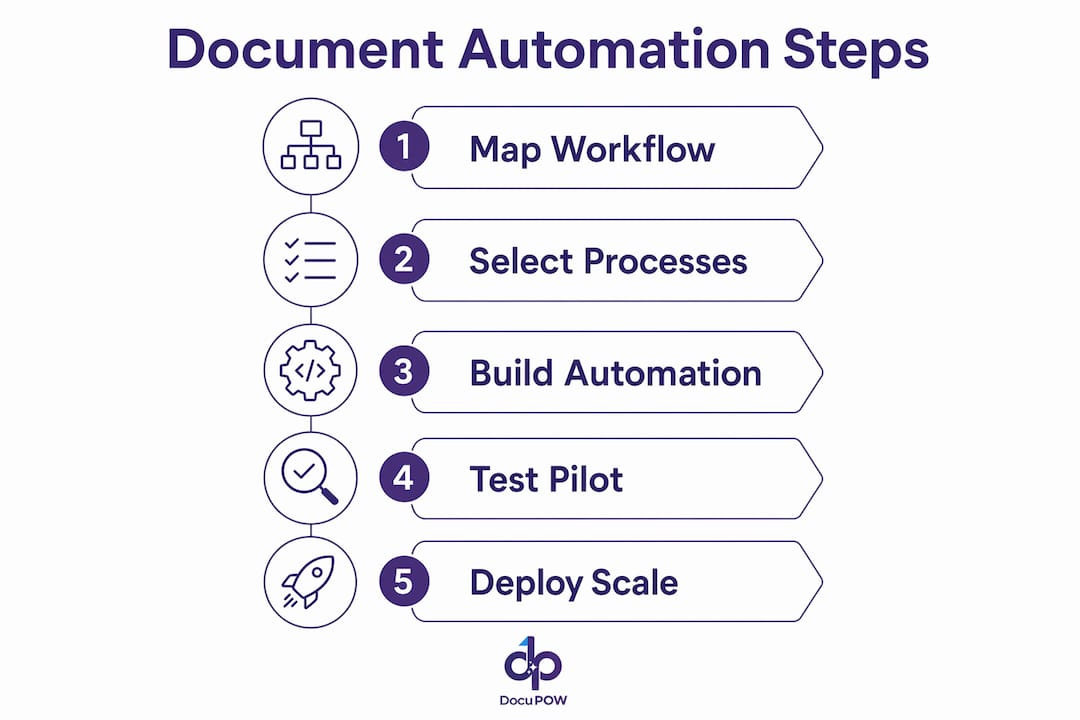
    Pro Tip: Before automating any document workflow, map the current process end to end. Automation accelerates whatever process exists. If the process is broken, automation makes it break faster.

    Why compliance and governance require document automation

    Compliance is the strongest organizational driver for document automation in IT environments. Consistent, auditable documentation is not optional under frameworks like SOC 2, ISO 27001, or HIPAA. Manual document handling introduces variation that auditors flag and regulators penalize.

    Automated generation from firm templates improves compliance consistency at scale. Every document produced from a validated template carries the correct structure, required fields, and approval signatures. That consistency reduces audit risk and peer review failures because the documentation matches the standard every time, not just when a careful employee happens to be working the file.

    Infographic illustrating key document automation process steps

    Governance in IT also requires controlling who can modify a document and when. Automation enforces those controls through permission layers, approval gates, and locked templates. A change request that bypasses the change advisory board cannot be submitted if the workflow requires CAB sign-off before the document advances.

    Versioning is equally critical. Regulatory audits frequently require IT teams to produce the exact version of a policy or procedure that was in effect on a specific date. Automated version control makes that retrieval straightforward. Manual version control, by contrast, depends on individual discipline and produces inconsistent results.

    1. Define document standards first. Establish the required fields, approval signatures, and retention periods before building any automation rule.
    2. Automate template enforcement. Lock document structures so staff cannot omit required sections or alter compliance language.
    3. Build approval gates into routing. Require documented sign-off at each governance checkpoint before a document advances to the next stage.
    4. Automate version archiving. Every published version should be timestamped and stored automatically, not saved manually by the document owner.
    5. Schedule compliance reviews. Set automated reminders to review and update policies on a defined cycle, keeping documentation current with regulatory changes.

    What are the biggest pitfalls in document automation projects?

    The most common failure in document automation is automating a process that does not actually exist as described. Without clear business process ownership, IT teams automate the imagined version of a workflow rather than what employees actually do. The result is an automated system that nobody uses because it does not match reality.

    A second major pitfall is the absence of measurable success criteria. Teams that cannot define what good looks like before they start cannot determine whether automation delivered value after it goes live. Tracking metrics like document cycle time, error rate, and approval turnaround must be established at the project outset, not retrofitted after deployment.

    Full automation without human review is a third failure mode. The best automation systems use a human-in-the-loop approach, where AI handles the bulk of processing and humans review exceptions. Documents with unusual structures, missing fields, or ambiguous data require human judgment. Removing that review layer to achieve full automation creates a system that fails quietly and at scale.

    • Skipping process mapping: Automating before documenting the actual workflow produces a system that reflects assumptions, not operations.
    • Ignoring integration complexity: Automation platforms must connect to existing IT systems. Underestimating that integration work delays projects and inflates costs.
    • Treating automation as a one-time project: Documentation must be continuously updated and integrated into workflows to remain effective. Static automation decays as processes evolve.
    • Framing automation as headcount reduction: Staff who fear job loss resist adoption. Positioning automation as a tool that frees people for higher-value work drives better outcomes.

    Pro Tip: Run a pilot on one high-volume, well-defined document workflow before scaling. A controlled pilot surfaces integration issues and process gaps without disrupting the broader organization.

    How IT teams successfully deploy document automation solutions

    Successful deployment starts with selecting the right workflows. Choosing processes to automate requires strategic selection based on impact, ownership, and measurable pain points. High-volume, repetitive workflows with clear rules and a single business owner are the best candidates. Complex, judgment-heavy workflows with multiple stakeholders are poor starting points.

    Business owners from finance, legal, and operations must define the automation rules, not IT alone. IT builds and maintains the technical infrastructure, but the people who live inside the process know where the exceptions occur and what the edge cases look like. That collaboration prevents the “imagined process” failure described above and produces automation that reflects actual operational needs.

    The data model matters as much as the workflow. Effective document automation treats lifecycle events as metadata, enabling search over rigid folder structures. IT teams that model documents as data objects, with attributes like document type, owner, status, and expiration date, build systems that remain searchable and auditable as volume grows. Teams that rely on folder hierarchies build systems that break under scale.

    Integration with existing infrastructure is non-negotiable. Automation platforms must connect to the ERP, ITSM, CRM, and communication tools already in use. Siloed automation that requires manual data transfer between systems defeats its own purpose. IT teams should evaluate connecting document automation to existing systems as a core requirement, not an afterthought.

    Deployment factor Strong approach Weak approach
    Process selection High-volume, rule-based, single owner Complex, judgment-heavy, multi-stakeholder
    Rule definition Business owners define logic IT team defines logic alone
    Data architecture Metadata-driven document objects Folder hierarchy storage
    System integration Native connectors to ERP, ITSM, CRM Manual data transfer between systems
    Ongoing maintenance Scheduled review cycles with assigned owners Set-and-forget deployment

    Automation also frees staff from repetitive tasks, enabling focus on judgment-intensive, higher-value work. That shift in capacity is the real return on investment. IT teams that position automation this way see stronger adoption because staff experience the benefit directly rather than viewing the system as a threat.

    Key Takeaways

    Document automation delivers its greatest value when IT teams own the infrastructure, involve business stakeholders in defining rules, and treat documents as structured data rather than static files.

    Point Details
    Efficiency gains are measurable Automating document generation and routing cuts cycle time and reduces errors across high-volume workflows.
    Compliance requires automation Consistent templates and automated approval gates reduce audit risk and enforce governance standards at scale.
    Process mapping prevents failure Automating an undefined or broken process accelerates the problem. Map actual workflows before building automation.
    Human review remains necessary A human-in-the-loop model handles exceptions that AI misclassifies, preventing silent failures at scale.
    Metadata beats folder structures Modeling documents as data objects with metadata attributes makes retrieval fast and audits manageable as volume grows.

    Document automation is not an IT project. It is an IT responsibility.

    I have watched IT teams treat document automation as a one-time implementation, hand it off to operations, and walk away. Within 18 months, the automation is outdated, staff have built workarounds, and the compliance benefits have evaporated. The organizations that get lasting value from document automation are the ones where IT maintains active ownership of the platform while business units own the content and rules.

    The collaboration piece is harder than the technology. Getting a finance director and a legal counsel to agree on a document template takes longer than configuring the workflow that enforces it. But that alignment is where the real work happens. IT’s role is to make that collaboration possible and to translate business requirements into a system that actually runs.

    I am also skeptical of any document automation project that does not include a human review layer. AI handles volume well. It handles exceptions poorly. The teams I have seen succeed are the ones that design for exceptions from day one, not the ones that discover exceptions after a compliance failure.

    Document automation is also the foundation that makes AI integration in IT workflows viable. You cannot build reliable AI-assisted processes on top of unstructured, inconsistently managed documents. The teams investing in high-volume document automation now are the ones that will deploy AI effectively in the next two years. The teams that skip this step will find their AI initiatives stalled by data quality problems.

    — Sameer

    See how DocuPOW handles document automation for IT teams

    DocuPOW is built for IT teams that need document automation to go beyond basic workflow routing. Its AI agents understand document context without relying on rigid templates, which means they handle the variability that breaks rule-based systems. DocuPOW connects to existing IT infrastructure, extracts structured data from unstructured files, and delivers real-time analytics that give IT leaders visibility into document performance across the organization.

    https://docupow.ai

    IT teams managing compliance requirements, high-volume document processing, or AI workflow integration will find the platform’s autonomous processing model directly relevant. The document process automation benefits page details how operations teams are applying these capabilities today. For a full view of the platform’s AI-driven document intelligence features, the DocuPOW product page covers the technical depth decision-makers need before evaluating a deployment.

    FAQ

    Why do IT teams manage document automation rather than operations?

    IT teams manage document automation because they control the infrastructure, integration points, and security architecture that automation depends on. Operations teams define the business rules, but IT owns the platform that enforces them.

    What is the human-in-the-loop model in document automation?

    The human-in-the-loop model assigns AI to process the majority of documents automatically while routing exceptions and ambiguous cases to human reviewers. This approach prevents errors from AI misclassification without requiring manual review of every document.

    How does document automation support IT compliance requirements?

    Automated templates enforce consistent document structure, required fields, and approval signatures across every document produced. That consistency reduces the variation that auditors flag and makes version retrieval straightforward during regulatory reviews.

    What is the biggest mistake IT teams make when implementing document automation?

    The most common mistake is automating a workflow that has not been properly mapped. IT teams that build automation around assumed processes rather than actual ones produce systems that staff bypass, which eliminates the compliance and efficiency benefits entirely.

    How does metadata tagging improve document management in IT?

    Metadata tagging models documents as data objects with attributes like type, owner, status, and expiration date. That structure makes documents searchable by any attribute combination, replacing folder hierarchies that become unmanageable as document volume grows.

  • AI Agents in Operational Decisions: 2026 Guide

    AI Agents in Operational Decisions: 2026 Guide

    AI agents are defined as autonomous coordinators of specialized analytical tools that decompose complex operational requests, route sub-problems to purpose-built models, and assemble governance-compliant recommendations at machine speed. The role of AI agents in operational decisions has moved from experimental to mission-critical in 2026, with organizations like KPMG, BCG, and MIT Sloan documenting concrete frameworks for deployment. This guide gives executives a direct map of the architecture, governance requirements, resource trade-offs, and real-world applications that determine whether an AI agent deployment succeeds or stalls.

    How do AI agents orchestrate complex operational decisions?

    AI agents orchestrate decision ecosystems by decomposing a single operational request into discrete sub-problems, each handled by a specialized agent built for that task. One agent may run supply optimization. Another runs simulation. A third handles analytics. An orchestrator coordinates all three, resolves conflicts between their outputs, and enforces policy precedence before assembling a final recommendation.

    This decentralized architecture is what separates modern AI agent systems from older monolithic models. A monolithic model tries to solve everything with one large system. A multi-agent architecture assigns the right tool to the right problem, which produces faster, more accurate outputs with clearer audit trails.

    The orchestrator’s job is not just coordination. It also enforces governance rules in real time, deciding which agent outputs are admissible and which require escalation. Without that layer, you get fast answers that may violate compliance requirements or contradict each other.

    • Decomposition: The orchestrator breaks a complex request (e.g., “optimize our Q3 procurement plan”) into sub-tasks: demand forecasting, supplier scoring, budget constraint modeling.
    • Routing: Each sub-task goes to the agent best equipped to handle it, whether that is an optimization engine, a generative model, or a simulation tool.
    • Conflict resolution: When two agents produce contradictory outputs, the orchestrator applies policy precedence rules to determine which recommendation takes priority.
    • Assembly: Final outputs are combined into a ranked set of recommendations with rationales, ready for executive review.

    Pro Tip: Map your existing decision workflows before deploying a multi-agent system. Agents can only decompose problems that are clearly defined. Ambiguous workflows produce ambiguous agent outputs.

    Narrow vs. wide decisions: how should AI agents be calibrated?

    Not every operational decision benefits from the same type of AI support. MIT Sloan recommends calibrating AI use to decision complexity, applying analytical optimization to narrow tasks and generative AI to wide decisions. Executives who overgeneralize AI across all decision types waste resources and introduce unnecessary risk.

    Team collaborating on AI decision calibration whiteboard

    The table below clarifies the distinction and guides deployment choices.

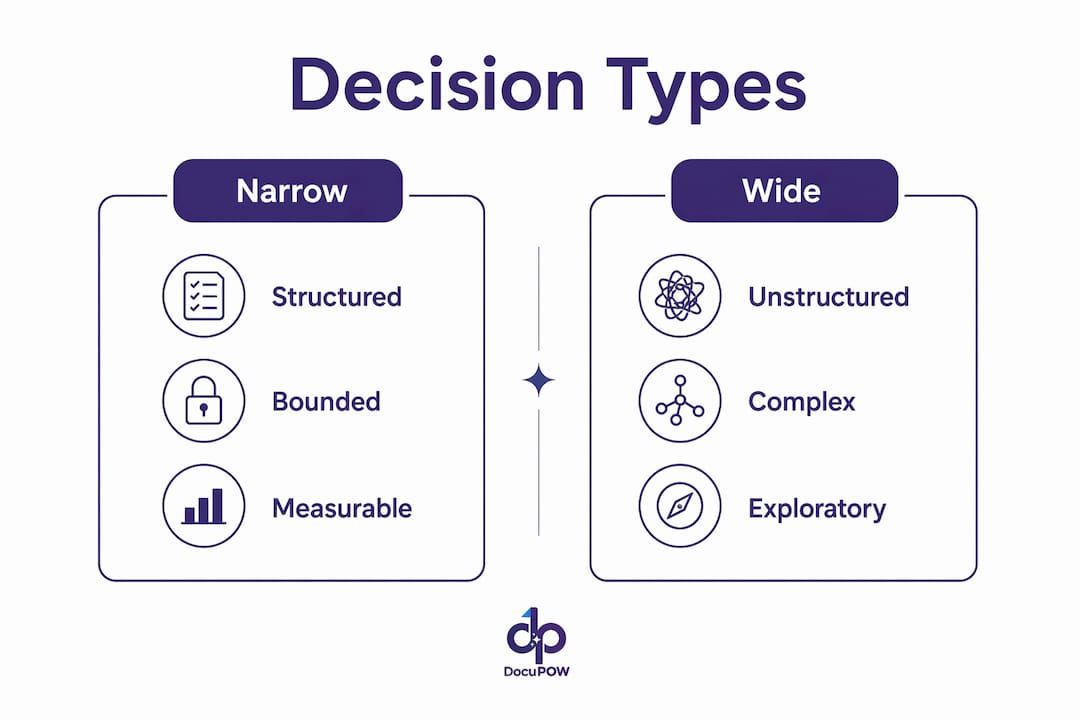
    Decision Type Characteristics Best AI Approach Example
    Narrow Structured, bounded, measurable Optimization models, analytical AI Inventory reorder point calculation
    Wide Ambiguous, exploratory, multi-stakeholder Generative AI, synthesis agents Strategic supplier diversification
    Hybrid Structured core with exploratory elements Combined orchestration Disruption response planning

    Infographic comparing narrow and wide AI decision types

    Narrow decisions have clear inputs, defined constraints, and measurable outcomes. Analytical AI and optimization models handle these well because the solution space is bounded. Wide decisions involve ambiguity, competing priorities, and judgment calls that require synthesis across many data sources. Generative AI agents excel here as exploration and synthesis tools, not as autonomous decision-makers.

    Hybrid decisions are the most common in practice. A procurement disruption, for example, has a structured cost component (narrow) and a strategic supplier relationship component (wide). The right architecture combines both agent types under a single orchestrator.

    Pro Tip: Before classifying a decision as narrow or wide, ask one question: “Can I write down every constraint that defines a correct answer?” If yes, it is narrow. If not, it is wide or hybrid.

    What governance requirements make AI agent deployment work?

    Enterprise AI agent deployment requires organizational readiness that goes well beyond technology capability. KPMG’s framework identifies three non-negotiable pillars: an updated IT operating model, clearly defined decision rights, and centralized monitoring for autonomous execution. Without all three, agents operate in a governance vacuum.

    The most common mistake executives make is treating human oversight as a one-time approval step. Human-in-the-loop supervision must be runtime and continuous. Approving an agent’s initial plan does not protect you from the emergent behaviors that arise as agents interact with live data and other agents at scale.

    Effective governance for AI agent systems requires the following:

    1. Embed governance as a pipeline operator. Controlled Agentic AI Systems that project actions into admissible space before execution provide auditability and replayability that approval gates cannot match.
    2. Define decision rights explicitly. Specify which decisions agents can execute autonomously, which require human confirmation, and which are always escalated to senior leadership.
    3. Implement centralized monitoring. A single observability layer across all agents lets you detect anomalies, track policy compliance, and intervene before errors compound.
    4. Design legible oversight moments. Plan-based oversight strategies reduce problematic agent actions by surfacing decision-critical moments to human reviewers in context, not after the fact.
    5. Avoid approval fatigue. Runtime governance that filters inadmissible actions automatically reduces the volume of human reviews to only the highest-stakes decisions.

    The goal is not to eliminate human judgment. The goal is to focus human judgment where it matters most, while agents handle the structured execution work that does not require it.

    What are the resource costs of multi-agent AI operations?

    Multi-agent AI systems consume significantly more compute than single-model deployments. Agentic AI workloads can involve up to 1,000 times more tokens and approximately 90 tool calls per scenario compared to standard model queries. That scale translates directly into higher cloud spend and longer latency if left unmanaged.

    The table below shows how key resource metrics shift between standard AI queries and agentic workloads.

    Metric Standard AI Query Agentic AI Workload
    Token volume Baseline Up to 1,000x higher
    Tool calls per scenario 1–3 ~90
    Latency Low Moderate to high
    Cost per decision Low Significantly higher

    These numbers are not a reason to avoid agentic AI. They are a reason to architect it carefully. Cost-aware orchestration means setting token budgets per sub-task, implementing stopping rules when utility checks show diminishing returns, and routing low-complexity sub-problems to smaller, cheaper models.

    Executives should treat token volume and tool call counts as primary performance budgets, the same way they treat compute costs in cloud infrastructure. An agent that runs 90 tool calls to answer a question that needed 10 is not more thorough. It is poorly designed. For a deeper look at agentic AI ROI benchmarks, the 2026 data shows clear patterns in where efficiency gains materialize and where overhead dominates.

    How do AI agents improve supply chain and procurement decisions?

    Supply chain and procurement are the two operational functions where the impact of AI agents is most documented and most measurable. BCG reports that AI agents assessed partial shipment options and production change scenarios in under an hour for senior management during a supply disruption. A human team performing the same analysis would typically need days.

    The mechanism behind that speed is agent-driven supply chain scenario evaluation: multiple specialized agents simultaneously model different response options, score them against cost, risk, and service-level constraints, and return a ranked list with rationales. Executives receive a structured decision brief, not raw data.

    Key applications where AI agents expand decision capacity in these functions include:

    • Disruption response: Agents evaluate dozens of rerouting, substitution, and production adjustment scenarios simultaneously, delivering ranked options within minutes.
    • Supplier risk scoring: Agents continuously monitor supplier financial health, geopolitical signals, and delivery performance to flag risks before they become disruptions.
    • Procurement negotiation support: Agents synthesize market pricing data, historical contract terms, and demand forecasts to recommend negotiation positions.
    • Demand-supply balancing: Agents coordinate across inventory, logistics, and production planning agents to recommend allocation decisions that minimize cost and stockouts simultaneously.

    The common thread across all four applications is speed and scope. AI agents do not just answer faster. They evaluate a wider range of options than any human team can process in the same time window. That expanded decision space is where the real operational value lives. Executives who want to understand how AI agent orchestration integrates with existing enterprise systems will find the technical architecture matters as much as the use case selection.

    Key takeaways

    AI agents deliver operational value only when governance, resource management, and decision-type calibration are built into the architecture from the start, not added after deployment.

    Point Details
    Orchestration architecture matters Decentralized multi-agent systems outperform monolithic models by routing sub-problems to specialized agents.
    Calibrate by decision type Apply optimization AI to narrow decisions and generative agents to wide or exploratory decisions.
    Runtime governance is non-negotiable One-time approval is insufficient; embed governance as a continuous pipeline operator with centralized monitoring.
    Resource costs require active management Token budgets and stopping rules prevent agentic workloads from generating excessive cost and latency.
    Supply chain delivers the clearest ROI BCG documents sub-hour scenario analysis that replaces multi-day human processes in procurement and logistics.

    Where most executives get AI agent deployment wrong

    I have watched organizations invest heavily in AI agent technology and then underperform expectations because they treated deployment as a technology project rather than an organizational change. The agents worked. The organization was not ready for them.

    The most consistent failure pattern is governance designed for the demo, not for production. A system that looks controlled in a sandbox behaves very differently when it is processing live procurement data, interacting with three other agents, and operating under time pressure. Emergent risks from large-scale agent interactions are not theoretical. Google DeepMind has flagged this as a serious concern for 2026 deployments. Executives need to take it seriously before they scale, not after.

    The second failure pattern is approval fatigue. Teams design human-in-the-loop oversight that requires sign-off on too many decisions. Reviewers start rubber-stamping. The oversight becomes theater. The fix is runtime governance that filters inadmissible actions automatically, so human reviewers only see decisions that genuinely require judgment. That requires investment in continuous human oversight design, not just a checkbox in the deployment plan.

    My honest recommendation: spend as much time on your governance model and IT operating model as you spend on selecting the AI technology itself. The technology is the easier problem.

    — Sameer

    How DocuPOW connects document intelligence to operational AI

    Operational AI agents are only as good as the data they work with. When critical information is locked in purchase orders, invoices, shipping documents, and contracts, even the best agent architecture produces decisions based on incomplete inputs.

    https://docupow.ai

    DocuPOW solves that problem directly. Its autonomous agents extract structured data from unstructured documents without rigid templates, feeding clean, context-aware data into your operational decision pipelines. For executives building AI-driven operations, DocuPOW provides the document intelligence layer that makes agent recommendations reliable. Explore the full range of document process automation benefits and see how DocuPOW integrates with enterprise AI workflows to improve both decision quality and operational efficiency.

    FAQ

    What is the role of AI agents in operational decisions?

    AI agents autonomously coordinate specialized analytical tools to decompose complex operational requests, enforce governance rules, and deliver ranked recommendations. Their core function is expanding decision speed and scope beyond what human teams can process manually.

    How do AI agents differ from traditional decision support tools?

    Traditional tools present data for humans to analyze. AI agents act on that data by routing sub-problems to specialized models, resolving conflicts between outputs, and assembling governance-compliant recommendations without waiting for human direction at each step.

    What governance model works best for AI agent deployments?

    KPMG’s framework recommends embedding controls directly into the action-execution pipeline, defining explicit decision rights, and maintaining centralized monitoring. Runtime governance outperforms approval-gate models because it filters inadmissible actions before they execute.

    How should executives measure AI agent performance?

    Track token volume, tool call counts, decision latency, and compliance rate as primary operational metrics. BCG’s supply chain examples show that speed of scenario evaluation and quality of ranked recommendations are the most meaningful business-level indicators.

    Are multi-agent AI systems too expensive for mid-size operations?

    Cost depends on architecture design, not system size. Implementing token budgets, stopping rules, and cost-aware routing keeps agentic workloads within budget. The Green Software Foundation documents that unmanaged agentic workloads can consume up to 1,000 times more tokens than standard queries, making deliberate resource design mandatory regardless of organization size.

  • Why Sales Teams Use Intelligent Document Tools

    Why Sales Teams Use Intelligent Document Tools

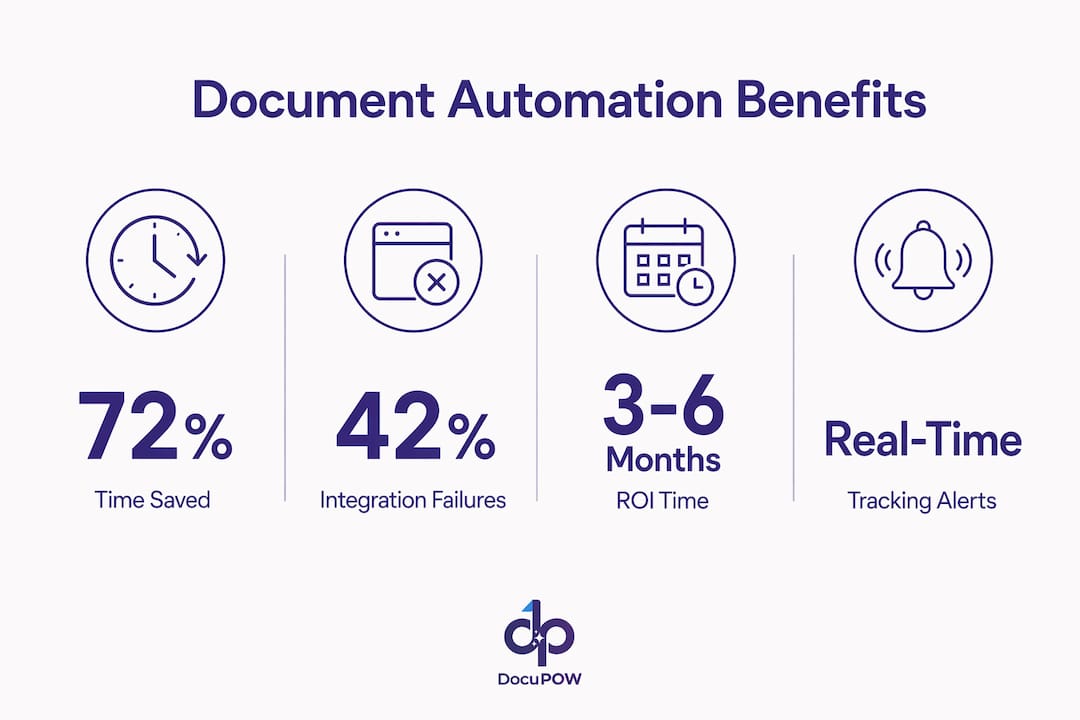
    Intelligent document tools are AI-enhanced platforms that automate the creation, extraction, routing, and tracking of sales documents like quotes, proposals, and contracts. Sales reps spend 72% of their time on non-selling tasks. That single number explains why sales teams use intelligent document tools at a scale that keeps accelerating. Platforms like PandaDoc, Docupilot, and Microsoft Power Automate have moved from “nice to have” to standard infrastructure for teams that want to close deals faster and with fewer errors. The industry term for the underlying technology is Intelligent Document Processing, or IDP. This article explains what IDP delivers, how it works inside a sales workflow, and how to adopt it without the common pitfalls.

    Why sales teams use intelligent document tools

    The core benefit is time. When nearly three-quarters of a rep’s day goes to administrative work, every hour reclaimed is an hour spent selling. Document automation cuts contract and proposal drafting time by 70–90% and reduces data entry errors by up to 90%. Those are not marginal gains. They represent a structural shift in how a sales team operates.

    Here is what that shift looks like in practice:

    • Speed to quote: A rep who once spent 45 minutes assembling a custom proposal can generate it in under five minutes using a CRM-connected template. That speed matters most when a prospect is comparing multiple vendors simultaneously.
    • Error reduction: Pricing errors in contracts create legal exposure and erode buyer trust. Template-based automation pulls verified data directly from your CRM, removing the copy-paste step where most mistakes happen.
    • Deal visibility: 40–60% of qualified B2B opportunities are lost to “no decision.” Document tracking tools show exactly when a prospect opens a proposal, which pages they read, and how long they spend on pricing. That data converts a vague follow-up call into a targeted conversation.
    • Compliance and consistency: Every document generated from an approved template meets legal and brand standards automatically. No rep goes rogue with an outdated pricing tier or an unapproved clause.

    Pro Tip: Set up document tracking alerts so your reps receive a real-time notification the moment a prospect opens a proposal. That is the best possible moment to call.

    The benefits of document automation extend beyond sales into legal, HR, finance, and procurement. For sales managers, that cross-functional reach means a single platform investment can justify itself across multiple departments.

    Close-up of sales rep receiving document alert

    How do intelligent document tools work inside sales workflows?

    IDP platforms combine several technologies to move a document from raw data to a signed, filed record without human intervention at each step. Understanding the mechanics helps you evaluate which tools fit your existing stack.

    1. AI-driven data extraction: The platform reads incoming documents, such as RFQs, purchase orders, or client intake forms, and extracts structured data using optical character recognition combined with natural language processing. AI semantic search allows the system to understand document context and intent, not just match keywords. That distinction matters for sales documents where the same concept appears in dozens of different phrasings.

    2. CRM-triggered document generation: When a deal moves to a specific pipeline stage in Salesforce or HubSpot, the platform automatically pulls the relevant account data and populates a proposal template. The rep reviews and sends. No manual data entry occurs between the CRM and the document.

    3. Routing and approval workflows: Complex deals often require legal or finance sign-off before a proposal goes out. Automation routes the document to the right reviewer based on deal size, product type, or territory, then tracks approval status in real time.

    4. E-signature and archiving: Once the client signs, the platform files the executed contract in the correct folder, updates the CRM record, and triggers any post-signature workflows like order creation or onboarding sequences. End-to-end workflow orchestration covering CRM-triggered generation through e-signature and archiving is now standard in platforms like n8n and Microsoft Power Automate.

    5. Engagement analytics: After a proposal is sent, AI analytics track buyer behavior inside the document, including page views, time on each section, and chatbot interactions. That data feeds directly into follow-up triggers.

    Pro Tip: Map your current document workflow on a whiteboard before selecting a tool. Identify every handoff point where data moves between systems. Those handoffs are where integration failures occur, and knowing them in advance lets you ask vendors the right questions.

    Integration is where most implementations stall. About 42% of implementation failures trace back to data transformation and format inconsistencies during system handoffs. API-level connections between your CRM and document platform are not optional. They are the foundation that prevents manual re-keying from creeping back in.

    Infographic showing key stats on document automation benefits in sales

    Which document tools and features are most effective for sales?

    The market splits into two categories: template-based document generation tools and full IDP platforms. Each serves a different level of complexity.

    Tool / Platform Best For Key Sales Feature
    PandaDoc Proposal and contract generation Real-time tracking, e-signature, CRM sync
    Docupilot High-volume document generation Template logic, API-first architecture
    Microsoft Power Automate Workflow orchestration across Microsoft stack Multi-system triggers, approval routing
    DocuPOW AI extraction from unstructured documents Template-free data extraction, autonomous agents

    Template-based tools like PandaDoc and Docupilot excel when your documents follow a predictable structure. They are fast to deploy and easy for reps to use without training. Full IDP platforms like DocuPOW handle the harder problem: extracting and acting on data from documents that arrive in inconsistent formats, such as client-supplied RFQs or third-party contracts.

    The features that move the needle most for sales teams are:

    • Real-time document tracking: Sales teams lose visibility the moment a proposal is sent without tracking. Knowing a prospect spent 12 minutes on the pricing page but skipped the case studies tells you exactly how to frame your next call.
    • AI chatbots embedded in proposals: Some platforms allow prospects to ask questions directly inside the document. The rep sees every question asked, which surfaces objections before the follow-up call.
    • Automated follow-up triggers: When a prospect opens a proposal for the third time without responding, an automated task or email sequence fires. That removes the guesswork from follow-up timing.

    AI-powered document intelligence is advancing from keyword matching to contextual understanding. For sales forecasting, that means the platform can flag contract language that historically correlates with delayed closes or price renegotiations.

    What are the best practices for adopting document automation in sales?

    Adoption fails most often when teams treat document automation as a software purchase rather than a process change. The technology is straightforward. The organizational discipline required to make it work is not.

    Start with the “two-of-three” rule to decide which documents to automate first. A document justifies automation investment if it meets at least two of these three criteria: it is generated frequently, it consumes significant rep time, or errors in it carry high risk. Quotes and renewal contracts almost always meet all three. One-off custom agreements often meet none.

    77% of companies struggle with data readiness when implementing automation. The “garbage in, garbage out” problem is real. If your CRM records are incomplete or inconsistently formatted, your automated documents will reflect those problems at scale. Audit your CRM data quality before you configure a single template.

    The practical steps for a successful rollout look like this:

    • Pilot with one document type: Choose your highest-volume proposal or quote template. Automate that single document end to end before expanding to other document types.
    • Build API connections, not workarounds: Require your vendor to demonstrate a live API connection to your CRM during the evaluation. Workarounds like CSV exports and manual uploads will fail within 90 days as data volumes grow.
    • Train on the workflow, not the software: Reps do not need to understand how the automation works. They need to understand what triggers it and what they are responsible for reviewing before sending.
    • Measure ROI at 90 days: Most teams see measurable returns within 3–6 months. Track drafting time per document, error rates on sent proposals, and proposal-to-close conversion rates before and after deployment.

    Pro Tip: Assign one sales ops team member as the document automation owner. Without a named owner, configuration drift and data quality issues accumulate silently until they cause a visible failure.

    The best sales teams treat document automation as an orchestration layer connecting multiple systems, not as a standalone tool. That mindset shift is what separates teams that see 30% efficiency gains from those that see 5%.

    Key takeaways

    Intelligent document tools deliver their highest value when deployed as an integrated workflow layer, not as isolated software, covering extraction, generation, tracking, and archiving across the full sales cycle.

    Point Details
    Time reclaimed from admin work Sales reps recover up to 72% of their time currently lost to non-selling tasks.
    Drafting speed and accuracy Automation cuts proposal drafting time by 70–90% and slashes data entry errors by up to 90%.
    Deal visibility through tracking Document tracking reduces B2B “no decision” losses by surfacing real-time buyer engagement data.
    Integration is the critical risk About 42% of implementation failures stem from poor system integration, not the software itself.
    Start narrow, then expand Pilot with your highest-volume document type and validate data quality before scaling automation.

    What i’ve learned after watching dozens of sales teams automate their documents

    Most sales managers I talk to approach document automation backwards. They evaluate tools first and figure out their process second. That sequence almost guarantees a painful implementation.

    The teams that get this right start by mapping every document touchpoint in their sales cycle, from the first quote request to the countersigned contract filed in their CRM. They identify where data moves between systems manually. Those manual handoffs are not just inefficiencies. They are error injection points, and they are where deals quietly die when a rep sends an outdated price list or a contract with the wrong entity name.

    What surprises most managers is how much deal intelligence is already sitting inside their sent proposals. They just cannot see it. A prospect who opens a proposal four times in two days and spends most of that time on the terms section is not a cold lead. They are a buyer working through an internal approval process. Without document tracking, your rep calls them on a random Tuesday and gets voicemail. With tracking, they call at the exact right moment with the right message.

    The future I see playing out is not just faster document generation. It is documents that actively participate in the sales process, surfacing objections, routing questions to the right rep, and feeding engagement signals back into forecasting models. DocuPOW’s approach of using autonomous agents that understand document context, rather than rigid templates, points directly at that future. The teams building those workflows now will have a structural advantage that compounds over time.

    — Sameer

    See how DocuPOW handles sales document automation

    Sales teams processing high volumes of quotes and contracts need more than a template generator. They need a platform that extracts data from any document format, connects to their existing CRM, and surfaces the insights that move deals forward.

    https://docupow.ai

    DocuPOW’s AI document automation platform uses autonomous agents to extract and act on data from unstructured documents without requiring rigid templates. That means your team handles client-supplied RFQs, third-party contracts, and non-standard purchase orders with the same speed and accuracy as your own templates. For teams managing high-volume document processing, DocuPOW’s architecture scales without adding manual review steps. Explore how DocuPOW fits your sales workflow and see the document intelligence features built specifically for sales and operations teams.

    FAQ

    What are intelligent document tools for sales teams?

    Intelligent document tools are AI-powered platforms that automate the creation, extraction, tracking, and filing of sales documents like quotes and contracts. They fall under the broader category of Intelligent Document Processing, or IDP.

    How much time do document tools save sales reps?

    Sales reps spend 72% of their time on non-selling tasks. Document automation directly reduces that burden by handling data entry, document generation, and follow-up routing automatically.

    How long does it take to see ROI from document automation?

    Most sales teams see measurable returns within 3–6 months of deployment. The fastest gains come from reducing drafting time and cutting errors on high-volume documents like proposals and renewal contracts.

    What is the biggest risk when implementing document automation?

    Integration failure is the leading cause of poor outcomes. About 42% of implementations fail due to data format inconsistencies between systems. Require API-level CRM integration from any vendor you evaluate.

    Do sales reps need technical skills to use these tools?

    No. Reps interact with the output, not the configuration. They review auto-populated documents, send them, and receive engagement alerts. The technical setup is handled by sales ops or IT during implementation.

  • Document Automation System Migration Guide 2026

    Document Automation System Migration Guide 2026

    A document automation system migration is the structured process of moving templates, workflows, metadata, and business logic from one document platform to another while preserving functional parity. Done right, this transition eliminates re-automation from scratch, protects years of workflow investment, and positions your organization to take full advantage of AI-driven processing. This document automation system migration guide covers every critical phase: pre-migration audits, template prioritization, tool selection, testing, and measuring ROI. Whether you’re upgrading a legacy system or moving to cloud document automation, the steps here apply directly to your project.

    What are the essential preparatory steps before migration?

    Preparation determines whether your migration succeeds or stalls. Structured checklists increase issue detection pre-production by 40–60% compared to ad-hoc approaches. That gap represents real problems caught before they reach your users.

    Start with a full audit of your existing document environment. Catalog every template, automation rule, metadata schema, and permission set. Insufficient metadata and permission analysis leads directly to security failures and retrieval breakdowns after go-live. These are not edge cases. They are predictable failures that a thorough audit prevents.

    Your document migration checklist should cover:

    • Template inventory: List every active template with its owner, usage frequency, and complexity rating
    • Metadata mapping: Document all field names, data types, and permission levels in the source system
    • Automation catalog: Record every conditional logic rule, macro, and workflow trigger
    • Vendor evaluation: Confirm your target platform includes conversion tools that preserve existing logic
    • Timeline and milestones: Set hard deadlines for each migration phase with named owners

    Vendor selection matters more than most teams realize. Choose a platform that provides native conversion utilities rather than forcing manual rebuilds. Platforms like DocuPOW use agentic AI to understand document context, which means they adapt to your existing structures rather than requiring you to conform to rigid new templates.

    Pro Tip: Weight your template inventory by business impact, not just volume. A template used 10 times per month that drives contract approvals outranks one used 200 times for low-stakes internal memos. Prioritize by value, not frequency alone.

    Hands comparing vendor brochures

    Skipping this phase creates compounding problems. Teams that rush into migration without a complete audit routinely discover orphaned automations, broken links, and missing metadata weeks after go-live. The cost of fixing those issues in production is always higher than the cost of finding them in pre-migration review.

    How to prioritize and convert templates efficiently

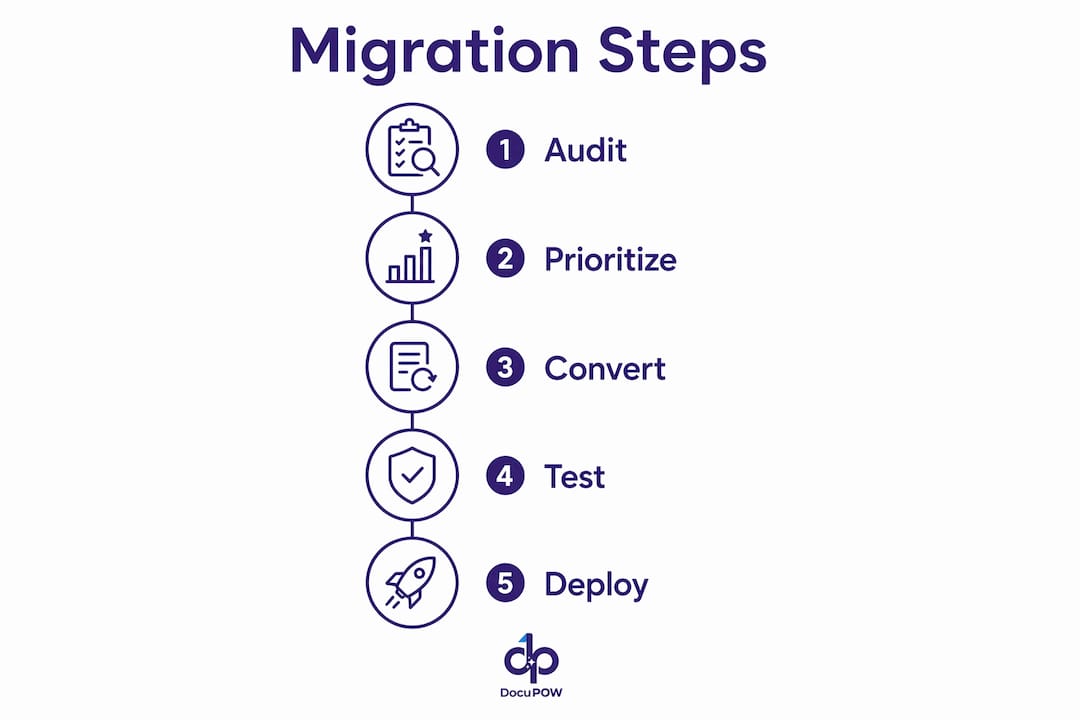
    Template prioritization is where most migrations win or lose. Migration success depends on template prioritization more than on technology selection alone. The 80/20 rule applies directly here: identify the top 20% of templates that generate 80% of your document volume, and migrate those first.

    Infographic showing migration steps from audit to deploy

    A phased approach works best for execution. Migrating 10–25 templates with complex logic takes approximately 2–3 weeks for an initial batch using specialized vendor services. That timeline gives you a realistic benchmark for planning your full rollout.

    Follow this sequence for each template batch:

    1. Audit for compatibility: Check for proprietary fonts, embedded macros, and conditional logic that may not transfer cleanly
    2. Flag technical risks: File path length limits and hidden macro dependencies are the most common causes of fidelity breaks during conversion
    3. Run vendor conversion tools: Use your platform’s built-in utilities before attempting manual rebuilds
    4. Validate outputs side by side: Compare converted template outputs against legacy outputs line by line
    5. Approve and archive: Sign off on each template before moving to the next batch

    The comparison below shows how a phased approach differs from a big-bang migration:

    Approach Risk Level Time to First Value Recovery if Issues Arise
    Phased (10–25 templates) Low 2–3 weeks Contained to current batch
    Big-bang (all at once) High Months System-wide rollback required

    Pro Tip: Test converted templates by generating identical inputs through both the legacy and new systems, then compare outputs character by character. Differences in spacing, field alignment, or conditional rendering are easy to miss in a visual review but will surface immediately in a structured diff.

    The migration phase is also the right time to deprecate obsolete templates. If a template hasn’t been used in 18 months, retiring it now reduces your ongoing maintenance burden and keeps your new system clean from day one.

    What tools and technologies accelerate a safe migration?

    Modern AI-driven platforms have fundamentally changed migration timelines. AI-driven automation stacks now deploy in weeks rather than the quarters that legacy implementations required. That compression is not just a convenience. It reduces the window during which your team operates two systems simultaneously, which is where most migration costs accumulate.

    Agentic AI represents the clearest break from legacy approaches. Traditional systems rely on rigid templates where every field and rule must be explicitly defined. Agentic AI enables contextual document understanding, meaning the system interprets document structure and intent rather than matching against fixed patterns. For organizations connecting document automation to existing systems, this flexibility dramatically reduces the manual configuration work that slows legacy migrations.

    The tools that matter most during a system upgrade include:

    • Content extraction engines: Automate the pull of data from legacy documents into structured formats
    • Conversion utilities: Transform legacy templates into formats compatible with your target platform
    • Validation frameworks: Run automated checks on converted outputs against defined quality criteria
    • Workflow orchestration tools: Manage the handoff between automated processing and human review queues

    The human-in-the-loop requirement deserves direct attention. 100% automation at go-live is rarely achievable or advisable. Every migration encounters document exceptions that fall outside automated handling. Define explicit roles for who reviews those exceptions and what the remediation path looks like before you start.

    The ROI case for automation tools is concrete. RPA automation cut one migration timeline from over 24 months down to 4 months. That is a 6x reduction in project duration, which translates directly into lower labor costs and faster time to operational benefit.

    “Workflow orchestration that integrates human review ensures the balance between automation speed and accuracy that production environments actually require.” — AGS Health Workflow Automation Case Study

    How to test, validate, and measure migration success

    Testing is not the final step. It is a continuous activity that runs parallel to migration from the first batch forward. The goal is functional parity: every converted template must produce outputs that match the legacy system in content, formatting, and behavior.

    Side-by-side output validation is the standard for quality assurance in document migration. Generate the same document from both systems using identical inputs, then compare results across formatting, field population, conditional logic, and link validity. Any discrepancy is a defect, not a cosmetic issue.

    Your testing workflow should address these criteria:

    • Completeness: All fields populate correctly with no missing data
    • Formatting fidelity: Fonts, spacing, headers, and tables render identically to legacy outputs
    • Link and reference validity: All internal document links and cross-references resolve correctly
    • Search functionality: Migrated documents are indexed and retrievable by expected metadata fields
    • User acceptance: End users from each department confirm the converted templates meet their operational needs

    Parallel run strategies reduce go-live risk significantly. Run both systems simultaneously for a defined period, typically two to four weeks, and compare outputs in real time. This approach catches issues that only surface under actual production conditions, such as edge-case inputs that automated testing does not cover.

    Track these metrics after go-live to measure whether the migration delivered its intended value: document processing time per transaction, error rates in automated workflows, user adoption rates by department, and time spent on manual exception handling. A successful migration shows measurable improvement in all four within 90 days of cutover.

    Document every issue found during testing, along with its root cause and resolution. That record becomes your lessons-learned library for the next migration phase and for ongoing system improvements.

    Key takeaways

    A successful document automation migration depends on structured preparation, priority-driven template conversion, and continuous validation rather than technology selection alone.

    Point Details
    Audit before you migrate Catalog all templates, metadata, and permissions to prevent post-migration security and retrieval failures.
    Prioritize by business value Migrate the top 20% of templates driving 80% of volume first to secure early ROI and stakeholder support.
    Use automation tools strategically AI-driven platforms and RPA can compress migration timelines from months to weeks when applied correctly.
    Plan for human review Define explicit roles for exception handling before go-live, since full automation at cutover is rarely achievable.
    Validate continuously Run side-by-side output comparisons from the first batch and track operational metrics for 90 days post-cutover.

    What i’ve learned running document automation migrations

    Most teams underestimate how much the migration phase reveals about their existing document environment. You go in expecting a straightforward lift-and-shift, and within the first audit you find templates no one has touched in three years, macros with undocumented dependencies, and metadata schemas that were never consistently applied. That discovery is uncomfortable, but it is also the most valuable thing the migration gives you.

    The teams that get the best outcomes are the ones who treat the migration as a cleanup project, not just a transfer project. They retire the templates that should have been retired years ago. They standardize metadata fields that were inconsistent across departments. They come out the other side with a leaner, better-documented system than they had before.

    The technical pitfalls I see most often are file path character limits and hidden macro dependencies. Both are easy to miss in a visual audit and both cause fidelity breaks that are frustrating to diagnose after the fact. Build a specific check for each into your pre-migration audit and you will avoid the majority of conversion failures.

    Stakeholder involvement early in the process is the other factor that separates smooth migrations from painful ones. When the finance team, legal team, and operations leads understand what is being migrated and why, they provide the template usage data and business context that makes prioritization decisions defensible. Without that input, you are guessing at what matters most.

    The shift toward agentic AI platforms like DocuPOW changes the long-term calculus here. Moving away from rigid template dependencies means your next migration, or your next system upgrade, will be significantly less painful. The document process automation benefits compound over time when the underlying system understands context rather than just matching fields.

    — Sameer

    How DocuPOW accelerates your migration project

    Organizations planning a document system upgrade need more than a checklist. They need a platform that reduces the manual work of conversion and handles the complexity of automating document workflows at scale.

    https://docupow.ai

    DocuPOW’s agentic AI processes documents without rigid template dependencies, which means your team spends less time rebuilding logic and more time validating results. The platform supports high-volume document processing from day one, with real-time analytics that give you visibility into migration progress and post-cutover performance. Whether you are migrating 50 templates or 5,000, DocuPOW’s autonomous agents adapt to your document structures rather than requiring you to conform to theirs. Schedule a demo with the DocuPOW team to see how the platform fits your specific migration timeline and document environment.

    FAQ

    What is a document automation system migration?

    A document automation system migration is the process of transferring templates, workflows, metadata, and business logic from one document platform to another while maintaining functional parity. The goal is to preserve existing automations without rebuilding them from scratch.

    How long does a document automation migration take?

    Migrating 10–25 complex templates typically takes 2–3 weeks per batch with specialized vendor support. Full migrations using AI-driven automation tools have been completed in as little as 4 months for projects that previously required over 24 months.

    What is the biggest risk in document migration?

    Failing to audit metadata and permissions before migration is the leading cause of post-migration failures. Security gaps and retrieval errors are the most common consequences, both of which are preventable with a thorough pre-migration audit.

    Should i migrate all templates at once or in phases?

    A phased approach is the standard recommendation. Migrating in batches of 10–25 templates limits risk exposure, allows for course correction between batches, and delivers usable results faster than a big-bang cutover.

    How do i know if my migration was successful?

    Measure document processing time, error rates, user adoption, and manual exception handling volume at 30, 60, and 90 days post-cutover. Improvement across all four metrics within 90 days indicates a successful transition.

  • Processing Throughput in Document AI: 2026 Guide

    Processing Throughput in Document AI: 2026 Guide

    Processing throughput in Document AI is defined as the rate at which a system processes documents or pages per unit of time, typically measured in documents per minute or pages per hour. This metric is the primary indicator of a Document AI pipeline’s capacity, not just its speed on a single file. For decision-makers managing high-volume workflows, understanding throughput at the stage level separates systems that scale from systems that collapse under load. Platforms like Google Document AI, along with OCR benchmarking frameworks, use throughput as the baseline for evaluating production readiness.

    How is processing throughput measured in document AI?

    Processing throughput is measured as the number of documents or pages a pipeline completes per unit of time, but that single number tells only part of the story. Stage-level metrics are the real signal. A pipeline typically moves documents through OCR, data extraction, and embedding generation. Each stage has its own throughput rate, and the slowest stage determines the ceiling for the entire system.

    The standard units for measuring document processing speed are:

    • Documents per minute (DPM) or documents per hour (DPH) for batch workflows
    • Pages per second (PPS) for high-frequency pipelines
    • Median queue wait time (P50) to measure typical delay between intake and processing
    • P95 queue wait time to capture the worst-case delay experienced by 95% of documents
    • Concurrency rate to understand how many documents the system handles simultaneously

    Queue wait time is the metric most teams ignore. End-to-end throughput drops when ingestion rates exceed downstream extraction capacity, creating hidden delays that never show up in API response logs. A system can report fast API times while documents sit in a backlog for minutes.

    Pro Tip: Slice your stage-level metrics by document type and region. A single average throughput number across mixed document types masks the bottlenecks that will hurt you at scale.

    Close-up of hands typing next to document AI metrics printouts

    The table below shows how to structure throughput measurement across a standard Document AI pipeline:

    Pipeline Stage Key Metric Unit Why It Matters
    OCR Pages processed Pages/second Bottleneck for scanned documents
    Data Extraction Fields extracted Records/minute CPU-bound; sensitive to document complexity
    Embedding Generation Vectors created Embeddings/second GPU-bound; bottleneck for text-native files
    Queue Wait Backlog delay P50/P95 seconds Reveals hidden capacity gaps
    End-to-End Total documents Docs/hour Capacity planning baseline

    What factors affect document AI throughput?

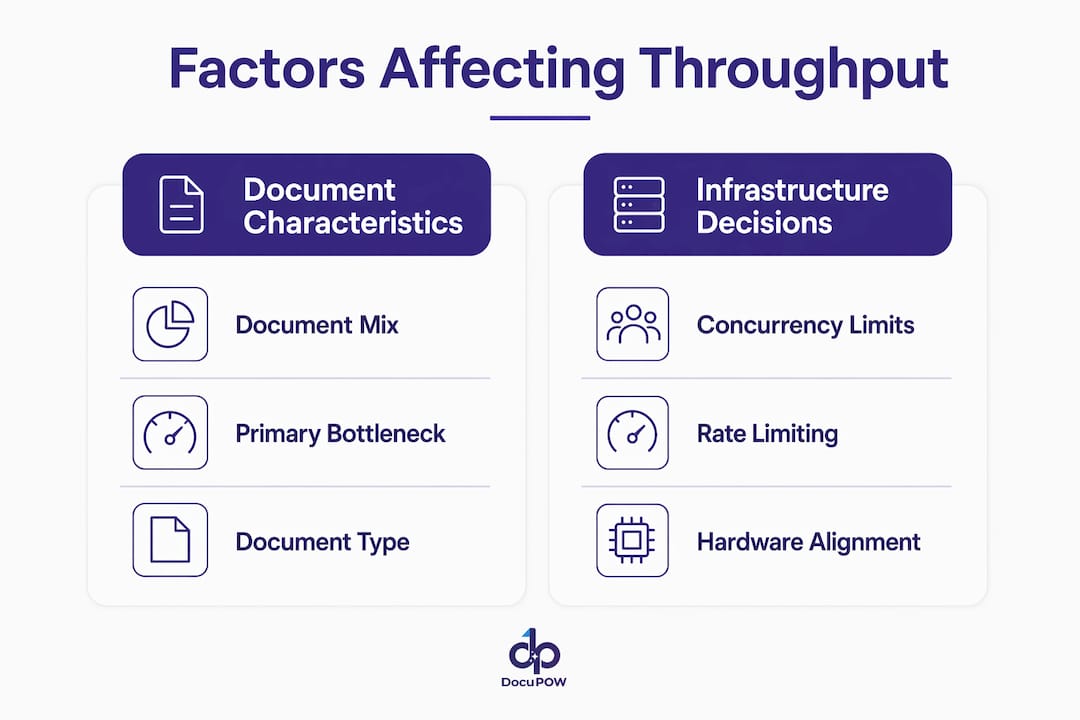
    The factors affecting Document AI performance fall into two categories: document characteristics and infrastructure decisions. Both shift the location of your bottleneck, often without warning.

    Infographic comparing document and infrastructure factors

    Document mix is the most underestimated variable. Throughput comparisons across vendors must normalize for document mix because scanned versus text-native documents influence capacity and manual review burden in fundamentally different ways. A pipeline optimized for clean, text-native PDFs will degrade sharply when you introduce high-DPI scans, handwritten forms, or multi-language tables.

    The bottleneck also shifts based on document type. For scanned documents, OCR is the primary constraint. For text-native files, embedding generation dominates. Example pipelines improve total processing time from 28 minutes to 17 minutes by accelerating both OCR and embedding on higher-tier GPUs. That 39% reduction comes entirely from identifying which stage was the actual bottleneck, not from general hardware upgrades.

    The comparison below shows how bottleneck location changes with document type:

    Document Type Primary Bottleneck Secondary Bottleneck Recommended Fix
    Scanned images (high DPI) OCR Queue wait GPU acceleration for OCR
    Text-native PDFs Embedding generation Extraction Higher-tier GPU, micro-batching
    Handwritten forms OCR + extraction Manual review queue Specialized OCR models
    Mixed document batches Varies by batch Queue management Stage-level monitoring

    Infrastructure decisions compound these effects. Scaling throughput by pushing concurrency too high can backfire due to overhead, throttling, or resource contention. Micro-batching, which accumulates small batches processed within strict latency windows, improves GPU utilization and reduces cost per page without sacrificing acceptable latency. This is the technique most teams skip because it requires more pipeline engineering upfront.

    Rate limiting adds another layer of complexity. Production endpoints use organization-level per-minute rate limits to maintain consistent throughput. When load exceeds these limits, queue wait times increase without triggering immediate failures. The system appears healthy in monitoring dashboards while documents pile up invisibly.

    Pro Tip: Never benchmark throughput with a single document type. Run your load tests with a representative sample of your actual document mix, including your worst-case files, before committing to a hardware or vendor configuration.

    How can businesses optimize document AI throughput?

    Optimizing throughput for document processing requires a structured approach. Speed improvements without measurement are guesses. Here is a practical sequence for decision-makers:

    1. Profile your document workload first. Categorize documents by type, page count, language, and image quality. This profile determines where your bottleneck will appear before you run a single test.

    2. Run load tests with latency percentiles. Load testing should include median and tail latency metrics with concurrency increases, not just single-request times. A system that handles 10 concurrent documents well may collapse at 100.

    3. Instrument every pipeline stage separately. Measuring only the final API response time misses queue delays that reduce effective throughput. Use end-to-end tracing tools to capture time spent at each stage, including time waiting in queue.

    4. Match hardware to your bottleneck. GPU acceleration delivers the most value for OCR and embedding stages. CPU-bound extraction steps benefit more from horizontal scaling and optimized parsing logic than from GPU investment.

    5. Implement micro-batching for GPU stages. Micro-batching strategies optimize GPU occupancy and minimize overhead, improving throughput without pushing latency beyond acceptable limits. This is especially effective for embedding generation in text-native document pipelines.

    6. Plan for burst tolerance explicitly. Planning for burst tolerance and the pipeline’s ability to recover from volume surges is a key operational consideration beyond average throughput. Define your acceptable queue backlog depth and build auto-scaling triggers around it.

    7. Integrate throughput metrics into operational dashboards. Stage-level throughput data should feed directly into workflow automation alerts. When a stage’s P95 queue wait exceeds your SLA threshold, the system should trigger scaling or rerouting automatically, not wait for a human to notice.

    For teams managing high-volume document processing, the difference between a well-tuned pipeline and an unmonitored one is not marginal. It shows up in missed SLAs, delayed financial close cycles, and compounding manual review backlogs.

    How does throughput relate to document processing speed?

    Throughput and latency are related but distinct metrics, and confusing them leads to poor infrastructure decisions. Latency measures how long a single document takes to process. Throughput measures how many documents a system processes per unit of time. A system can have low latency on individual documents and still deliver poor throughput under real-world load.

    The relationship breaks down under concurrency. High throughput at low concurrency can hide unacceptable waits under realistic loads. When 500 documents arrive simultaneously, even a fast system will queue most of them. The user experience depends on P95 and P99 wait times, not on the median.

    The right metric depends on your use case:

    • Interactive applications (real-time data extraction, live document review) require low latency. P50 and P95 response times matter most.
    • Batch workflows (overnight invoice processing, bulk contract analysis) require high throughput. Documents per hour and queue recovery time matter most.
    • Mixed workloads require both. You need throughput capacity for the batch load and latency headroom for the interactive requests that arrive during the same window.

    Throughput evaluation must focus on tail latency percentiles such as P95 and P99 alongside concurrency thresholds to avoid operational collapse hidden by averages. A system that looks healthy at P50 can be failing 5% of your highest-priority documents. For compliance-sensitive workflows, that 5% is not acceptable. Aligning throughput goals with SLA commitments requires tracking the full distribution of processing times, not just the average.

    Key takeaways

    Effective Document AI throughput management requires stage-level measurement, hardware alignment, and tail latency monitoring to prevent hidden bottlenecks from undermining SLA performance.

    Point Details
    Measure stage by stage Track OCR, extraction, and embedding throughput separately to locate the actual bottleneck.
    Include queue wait time P50 and P95 queue metrics reveal hidden delays that API response times never capture.
    Match hardware to bottleneck GPU acceleration helps OCR and embedding; CPU scaling helps extraction-heavy pipelines.
    Normalize for document mix Throughput benchmarks are only valid when tested against your actual document distribution.
    Plan for burst scenarios Define acceptable queue backlog depth and automate scaling before peak loads arrive.

    Why most teams measure throughput wrong

    Most teams I work with measure throughput by looking at API response times and calling it done. That is the single most common mistake in Document AI operations, and it is expensive.

    The real problem is that queue wait time is invisible unless you instrument for it specifically. I have seen pipelines where the API reports a 2-second response time while documents are waiting 4 minutes in the intake queue. The team believes the system is fast. The business is missing its SLA by a factor of ten. End-to-end tracing is not optional. It is the only way to see what is actually happening.

    The second issue is bottleneck blindness. Teams optimize OCR because that is the obvious target. Then they upgrade their OCR hardware and discover that embedding generation is now the constraint. The bottleneck shifted, and they did not see it coming because they were not tracking stage-level metrics. Adaptive measurement, where you monitor every stage continuously and alert on relative changes, solves this. It requires more setup, but it pays back immediately when you avoid a capacity crisis during a peak processing window.

    My advice for decision-makers: before you spend on hardware or new vendors, spend two weeks instrumenting your current pipeline properly. The data will tell you exactly where to invest. Aligning throughput goals with business outcomes, such as financial close timelines or compliance deadlines, also changes the conversation. Throughput is not a technical metric. It is a business metric with a direct line to cost and risk.

    — Sameer

    How DocuPOW helps you hit your throughput targets

    Processing throughput is only as useful as the platform tracking and acting on it. DocuPOW’s AI document automation platform is built for organizations running high-volume, complex document workflows where stage-level performance directly affects financial visibility and operational decisions.

    https://docupow.ai

    DocuPOW’s autonomous agents process documents without rigid templates, which means throughput stays consistent even as your document mix changes. Real-time analytics surface stage-level bottlenecks before they become SLA violations. For teams in industries like real estate document workflows or manufacturing, where document volume spikes are predictable and costly, DocuPOW’s platform provides the throughput monitoring and back-office automation needed to scale without adding headcount. Explore DocuPOW’s high-volume processing strategies to see how throughput optimization translates into measurable business results.

    FAQ

    What is processing throughput in document AI?

    Processing throughput in Document AI is the rate at which a system processes documents or pages per unit of time, measured in documents per minute or pages per hour. It reflects the system’s total capacity across all pipeline stages, not just the speed of a single document.

    How do you measure throughput in a document AI pipeline?

    Measure throughput at each pipeline stage separately, including OCR, extraction, and embedding, using pages per second and queue wait time percentiles such as P50 and P95. Measuring only the final API response time misses hidden queue delays that reduce effective throughput.

    What is the difference between throughput and latency in document processing?

    Latency measures how long a single document takes to process. Throughput measures how many documents a system handles per unit of time. High throughput does not guarantee low latency under concurrent load, which is why both metrics must be tracked together.

    Why does document type affect throughput so much?

    Scanned documents make OCR the primary bottleneck, while text-native PDFs shift the constraint to embedding generation. Throughput benchmarks that ignore document mix overestimate real-world capacity and underestimate the impact of accuracy problems on manual review queues.

    How can businesses improve document AI throughput without adding cost?

    Micro-batching GPU stages, profiling your document workload before scaling, and instrumenting queue wait times at each pipeline stage are the highest-return improvements. Identifying the actual bottleneck stage before investing in hardware prevents spending on the wrong constraint.

  • The Role of AI in Manufacturing Documents in 2026

    The Role of AI in Manufacturing Documents in 2026

    The role of AI in manufacturing documents is to convert manual, error-prone paperwork into automated, auditable, and accurate workflows that scale across global operations. Intelligent document processing (IDP), the recognized industry term for this technology, combines computer vision, natural language processing (NLP), and agentic AI to ingest, classify, extract, and validate documents with 95%+ extraction accuracy. For manufacturing professionals managing inspection reports, certificates of conformance, work orders, and supplier invoices, this shift is not theoretical. It is operational, measurable, and already delivering compliance advantages that manual processes cannot match.

    How does AI-enabled intelligent document processing work in manufacturing?

    AI-enabled IDP processes manufacturing documents by layering multiple AI techniques into a single workflow rather than applying one algorithm to every document type. Computer vision reads scanned forms, handwritten inspection sheets, and mixed-format PDFs. NLP interprets the meaning of extracted text, maps it to data fields, and flags anomalies. Agentic AI platforms then route the structured output to downstream systems such as ERP, PLM, or quality management software without human intervention.

    The document types IDP handles in manufacturing are wide-ranging:

    • Purchase orders and supplier invoices validated against approved vendor databases
    • Inspection reports and non-conformance records classified by product line or facility
    • Certificates of calibration and training records matched to regulatory requirements
    • Work orders and maintenance logs routed to the correct production team
    • Bills of materials cross-referenced against engineering change orders

    The workflow typically follows a defined sequence. Raw documents enter a pre-processing layer that separates text, handwriting, and diagrams before any AI model touches the content. Confidence scoring then assigns a reliability rating to each extracted field. High-confidence outputs route automatically; low-confidence fields escalate to a human reviewer. This architecture is what allows automation of 70-80% of manual document tasks while keeping human judgment in the loop for edge cases.

    Contextual learning improves classification over time. When a reviewer corrects a misclassified document, the model updates its understanding of that document type. Over weeks, the system recognizes facility-specific formats, supplier-specific layouts, and regulatory-specific terminology without requiring template reconfiguration.

    Hands scanning manufacturing documents at workstation

    Pro Tip: Start IDP deployment on a single, high-volume document type, such as supplier invoices or calibration certificates, before expanding. A focused pilot generates measurable ROI data and exposes pre-processing gaps before they affect critical compliance records.

    What is AI’s impact on compliance and audit readiness?

    Compliance documentation in manufacturing is where AI delivers its most deterministic value. AI document control produces binary outputs: either a clause complies with the referenced standard or it does not. This removes the interpretive ambiguity that auditors and quality managers spend hours resolving manually.

    AI-driven compliance systems accomplish the following in sequence:

    1. Capture and classify incoming compliance documents, including SOPs, HACCP plans, calibration records, and training logs, by regulatory category and revision status.
    2. Validate procedural usage by cross-referencing active document versions against approved master lists, flagging any outdated procedures still in circulation.
    3. Monitor continuously by scanning for expiration dates on certifications, training completions, and equipment calibration cycles, then escalating alerts when validations fail.
    4. Generate audit-ready evidence files organized by regulatory requirement, with clear chains of custody showing who approved each document and when.

    “Implementation cycles for AI document control are measured in weeks, not months, and the ROI is visible directly in audit outcomes.” — Quality Digest

    The practical impact on audit preparation is significant. Digital structured records replace physical binders, and a query replaces a manual binder pull during an FDA or ISO inspection. Audit nonconformances drop because version control is enforced automatically rather than relying on staff to pull the correct revision. For food manufacturers, pharmaceutical producers, and automotive suppliers operating under strict regulatory frameworks, this capability alone justifies the investment in AI-driven document processes.

    AI compliance automation also generates continuous monitoring dashboards that give quality managers real-time visibility into document status across multiple facilities. A calibration certificate expiring in 14 days triggers an alert today, not after the auditor finds it.

    Infographic showing AI document workflow steps

    What are the risks in AI-driven document workflows?

    AI-driven document workflows carry real risks that manufacturing teams must address before full deployment. The most underreported risk is silent content corruption. Frontier large language models corrupt approximately 25% of original document content during prolonged delegated workflows, and this degradation increases with document length and the presence of distracting files. Adding agentic tools does not prevent this problem because it is inherent to transformer architectures.

    The table below maps the primary risk categories against their causes and mitigations:

    Risk Cause Mitigation
    Silent content corruption LLM processing of long documents Separate retrieval from editing; use human diffs
    Extraction hallucinations Messy or mixed-format input documents Pre-processing layer before AI ingestion
    Misclassification errors Insufficient training data for document type Confidence scoring with human escalation
    Governance failures No audit trail on AI-generated outputs NIST AI RMF-aligned policy controls
    Version control drift AI editing approved documents without approval Lock editing behind human approval workflows

    Messy input documents are the second major failure point. A scanned form with handwritten annotations, embedded diagrams, and faded text will produce unreliable extractions if fed directly to an AI model. Document pre-processing that separates text, handwriting, and diagrams before ingestion reduces errors and prevents AI from hallucinating critical fields such as part numbers, lot codes, or approval signatures.

    Pro Tip: Treat every document entering your AI workflow as potentially corrupted at the source. Build a pre-processing validation layer that normalizes format, resolution, and structure before any extraction model runs. This single step prevents the majority of downstream accuracy failures.

    Human-in-the-loop verification is not optional in manufacturing contexts. When an AI system edits a controlled document, a qualified reviewer must compare the original and the modified version using a diff tool before the change is committed. Digitizing without this governance layer creates a compliance liability, not an advantage.

    What are the best practices for implementing AI in manufacturing document management?

    Successful AI adoption in manufacturing document management follows a governance-first architecture rather than a technology-first one. Aligning with the NIST AI Risk Management Framework means applying its four functions: Govern, Map, Measure, and Manage. This translates to defining acceptable use policies for AI document editing, mapping which document types carry the highest risk, measuring extraction accuracy against ground truth, and managing exceptions through escalation workflows.

    The following practices separate successful implementations from failed pilots:

    • Build a governed intake layer. Every document entering the AI system passes through pre-processing, confidence scoring, and source citation before any downstream action. Raw, unvalidated documents never reach production workflows.
    • Integrate AI with existing PLM and CCMS platforms. Structured content architectures that merge PLM and CCMS enable AI to retrieve accurate manufacturing document information in real time. Machine-readable content organized by topics and metadata relationships is what makes conversational AI retrieval reliable.
    • Connect AI to BPM and RPA systems. Workflow automation tools handle the routing, approval, and archiving steps that follow extraction. This end-to-end connection is what produces the 70-80% reduction in manual work.
    • Separate retrieval from editing. Retrieval using vector embeddings is low-risk and appropriate for AI automation. Editing controlled documents requires human approval and a documented diff before any change is committed.
    • Measure ROI against compliance outcomes. Track audit nonconformances, document retrieval time, and manual processing hours before and after deployment. These metrics communicate value to operations leadership and justify expansion.

    Implementation cycles for AI document control run in weeks when the scope is focused. A phased approach, starting with one document type and one facility, generates the evidence base needed to scale confidently. Avoid the common mistake of deploying AI across all document types simultaneously before governance policies are tested. AI implementation mistakes at the governance layer are far more expensive to fix than delayed rollouts.

    Key takeaways

    AI in manufacturing document management delivers measurable compliance, accuracy, and efficiency gains only when governance, pre-processing, and human verification are built into the workflow from the start.

    Point Details
    IDP accuracy benchmark AI-enabled IDP achieves 95%+ extraction accuracy when pre-processing layers are in place.
    Compliance automation value AI generates audit-ready evidence files and continuous compliance alerts, reducing nonconformances.
    Silent corruption risk LLMs corrupt roughly 25% of content in long delegated workflows; separate retrieval from editing.
    Governance alignment Align AI document workflows with the NIST AI Risk Management Framework before scaling.
    Phased implementation Start with one high-volume document type to validate accuracy and governance before expanding.

    Why most manufacturing teams underestimate the pre-processing problem

    I have watched manufacturing teams invest heavily in AI document platforms and then spend the first six months troubleshooting extraction failures that had nothing to do with the AI model itself. The documents were the problem. Scanned PDFs with mixed handwriting, embedded schematics, and inconsistent field layouts will defeat even a well-trained model if they enter the pipeline raw.

    The instinct is to blame the AI vendor and demand a better model. The actual fix is almost always upstream: clean the input before the model ever sees it. Pre-processing is unglamorous work, but it is the single highest-leverage investment in any manufacturing document automation program.

    I am also skeptical of teams that skip human-in-the-loop verification because it feels like it defeats the purpose of automation. It does not. Automation handles volume; human review handles risk. In a regulated manufacturing environment, a single corrupted controlled document can trigger a recall, a warning letter, or a failed audit. The cost of that outcome dwarfs the cost of a reviewer spending 30 seconds approving a diff.

    What I find genuinely exciting about 2026 is that agentic AI platforms are now capable of continuous compliance monitoring at a scale no human team can match. Expiring certifications, outdated SOPs, and missing training records surface automatically before an auditor finds them. That is a real operational advantage, and it is available today to any manufacturer willing to build the governance layer first.

    Start with structured digital records. Build the pre-processing layer. Align with NIST AI RMF. Then automate in phases. The teams that follow this sequence are the ones reporting measurable audit improvements within a quarter.

    — Sameer

    How DocuPOW supports manufacturing document automation

    DocuPOW is built specifically for the document complexity that manufacturing operations generate every day. Its autonomous agents understand document context without relying on rigid templates, which means inspection reports, certificates, and supplier invoices are processed accurately even when formats vary across facilities or suppliers.

    https://docupow.ai

    For manufacturing teams focused on compliance and audit readiness, DocuPOW’s manufacturing document automation platform delivers real-time extraction, confidence scoring, and continuous compliance monitoring in a single governed workflow. Pre-processing, human escalation, and audit trail generation are built in, not bolted on. If you are evaluating how to reduce manual processing time and improve audit outcomes, explore DocuPOW’s document process automation benefits to see where your operations can gain the most ground.

    FAQ

    What is intelligent document processing in manufacturing?

    Intelligent document processing (IDP) is the AI-driven method for ingesting, classifying, extracting, and routing manufacturing documents using computer vision and NLP. It processes thousands of documents automatically and outputs structured data for ERP, PLM, and quality management systems.

    How does AI improve compliance documentation?

    AI captures, classifies, and validates compliance documents continuously, generating audit-ready evidence files and escalating alerts when certifications expire or procedures fall out of compliance. This replaces manual binder reviews with real-time monitoring.

    What is the biggest risk of using AI for manufacturing documents?

    The most significant risk is silent content corruption. Frontier LLMs corrupt roughly 25% of original document content during long delegated workflows, which makes separating document retrieval from editing, and requiring human approval for edits, a non-negotiable governance requirement.

    How long does AI document control implementation take?

    Implementation cycles for focused AI document control deployments are measured in weeks, not months, particularly when scoped to a single document type or facility before scaling.

    What governance framework should manufacturers use for AI documents?

    The NIST AI Risk Management Framework provides the most applicable structure, covering Govern, Map, Measure, and Manage functions that align directly with the audit trail and policy compliance requirements of manufacturing document workflows.

  • Types of Financial Document Automation Tools Explained

    Types of Financial Document Automation Tools Explained

    Financial document automation tools are software solutions that automate the processing, data extraction, and management of financial documents to improve efficiency and accuracy in business workflows. The category spans everything from optical character recognition engines that pull data from scanned invoices to full contract lifecycle management platforms that govern every clause in a vendor agreement. Understanding the distinct types of financial document automation tools available is the first step toward selecting the right solution for your organization. The wrong choice wastes budget; the right one can cut document processing time by 70% to 90% and deliver ROI within three to six months.

    Types of financial document automation tools and their core functions

    Financial process automation covers a broader set of categories than most decision-makers initially expect. Each tool type solves a specific problem in the document workflow, and knowing the differences prevents you from buying an accounts payable platform when what you actually need is a contract assembly engine.

    1. OCR and AI-powered data extraction engines

    Data extraction tools use optical character recognition (OCR) and machine learning to read, parse, and structure data from unstructured financial documents such as invoices, receipts, and bank statements. Traditional OCR relies on fixed templates and breaks when a vendor changes their invoice layout. AI-powered extraction engines, by contrast, understand document context and adapt without manual reconfiguration. DocuPOW uses autonomous agents that identify data fields by meaning rather than position, which eliminates the template dependency that makes legacy OCR brittle in high-volume environments.

    Developer typing code for AI data extraction

    2. End-to-end accounts payable automation

    Accounts payable (AP) automation platforms handle the full invoice lifecycle: capture, validation, three-way matching against purchase orders and receipts, approval routing, and payment scheduling. Financial institutions automate invoice management to reduce manual data entry and accelerate approvals, directly improving vendor relationships and cash flow visibility. Tools in this category typically integrate with ERP systems like SAP, Oracle, and Microsoft Dynamics to push validated data directly into the general ledger without human intervention.

    3. Expense management automation

    Expense tools automate the capture, categorization, and reimbursement of employee spending. Platforms in this space connect to corporate card feeds, scan receipts via mobile, and apply policy rules automatically to flag out-of-policy submissions before they reach a manager. The advantages of automated expense tracking include faster reimbursement cycles and a real-time view of discretionary spending that manual spreadsheet processes simply cannot provide. For finance teams managing hundreds of expense reports per month, this category alone can recover dozens of hours of review time each week.

    4. Contract lifecycle management platforms

    Contract lifecycle management (CLM) platforms govern the creation, negotiation, execution, and renewal of contracts. Top enterprise CLM platforms include Conga, DocuSign CLM, Icertis, Ironclad, and Sirion, each offering AI-assisted clause analysis, obligation tracking, and integration with Salesforce or SAP. The critical differentiator in this category is template governance. Centralized template management separates true CLM automation from simply storing Word files in SharePoint, because it enforces pre-approved language across every contract generated in the organization.

    Pro Tip: When evaluating CLM platforms, ask vendors specifically how they handle template versioning and what happens to in-flight contracts when a clause is updated. The answer reveals whether their governance model is real or cosmetic.

    5. Template-driven document assembly tools

    Document assembly tools generate financial documents, such as proposals, statements of work, and loan agreements, by merging pre-built templates with data pulled from CRM or ERP systems. PandaDoc handles basic automation for sales and finance teams, while Conga and Nintex serve complex enterprise document needs requiring conditional logic, multi-party inputs, and output in multiple formats. The speed advantage is measurable: specialized firms report contract processing times dropping from days to as little as 18 minutes after deploying assembly automation.

    6. Automated financial reporting tools

    Reporting automation tools pull data from accounting systems, apply formatting rules, and produce recurring financial reports, including monthly close packages, board decks, and regulatory filings, without manual compilation. QuickBooks automates invoice generation and basic financial summaries for small and mid-sized businesses. Enterprise finance teams typically use tools that connect directly to their data warehouse and render reports in Excel, PDF, or web dashboards on a scheduled basis. The value is consistency: every report uses the same data source and the same calculation logic, which eliminates the version-control chaos that plagues manually assembled reports.

    7. Document management systems with workflow automation

    Document management systems (DMS) like SharePoint, M-Files, and OpenText provide the storage and retrieval layer, but the more capable platforms add workflow automation on top. This means a document can trigger an approval chain, notify a reviewer, escalate on deadline, and archive itself to the correct retention policy folder without anyone managing the process manually. For finance teams, this matters most during audit preparation, when the ability to retrieve a specific version of a document with its full approval history in seconds is the difference between a smooth audit and a stressful one.

    8. E-signature and digital execution platforms

    E-signature tools are often the entry point for organizations beginning to automate financial documents. DocuSign and Adobe Acrobat Sign handle legally binding execution of contracts, loan documents, and purchase agreements. The automation value goes beyond the signature itself: these platforms track document status in real time, send automated reminders, and feed completion data back into CRM or ERP systems. For high-volume transaction environments, removing the print-sign-scan cycle alone can save several days per deal.

    9. Integration middleware and API connectors

    No financial document automation tool operates in isolation. Integration middleware platforms like MuleSoft, Workato, and Zapier connect document tools to the broader finance technology stack, including ERP, CRM, banking APIs, and tax systems. Connecting document automation to existing systems is the step most organizations underestimate during vendor selection. A tool with strong native integrations reduces implementation time and ongoing maintenance costs significantly compared to one that requires custom API development for every connection.

    How automation cuts costs and strengthens compliance

    The financial case for document automation is direct. Implementing automation lowers operational costs by 30% to 40% in mid-sized companies by reducing manual labor and errors. That figure becomes more concrete when you consider that preventing even a conservative 2% of error-related rework often covers the full software investment cost. This means the ROI calculation for most organizations is not speculative; it is a matter of measuring current rework volume and mapping it against tool pricing.

    Compliance is the less-discussed but equally important benefit. Automation enforces pre-approved templates, which eliminates the risk of outdated or legally incorrect language appearing in contracts and financial documents. When a regulatory requirement changes, the update happens once in the central template library and propagates to every document generated afterward. Without automation, that same update requires tracking down every team member who has a local copy of the old template and hoping they make the change correctly.

    “Automation is not only a time-saver but a critical risk mitigation strategy through enforced template use and compliance controls.” — Ironclad

    Comparing leading tools across categories

    The table below maps the most widely deployed financial document automation tools to their primary use case, key strength, and ideal buyer profile.

    Tool Category Key strength Best for
    DocuSign CLM Contract lifecycle management AI clause analysis, Salesforce integration Mid-market to enterprise legal and finance teams
    Conga Document assembly and CLM Complex conditional logic, Salesforce-native Enterprise revenue operations teams
    Ironclad CLM Workflow automation, legal collaboration In-house legal teams with high contract volume
    PandaDoc Document assembly and e-signature Ease of use, fast deployment SMB sales and finance teams
    QuickBooks Automated financial reporting Accounting integration, invoice automation Small and mid-sized business finance teams

    A few observations from this comparison. Ironclad and DocuSign CLM both serve CLM needs but differ in buyer profile: Ironclad targets legal-led workflows while DocuSign CLM integrates more deeply into sales-driven contract processes. PandaDoc is the fastest to deploy but lacks the governance depth that enterprise compliance requirements demand. QuickBooks automates well within its accounting ecosystem but is not a substitute for a dedicated document assembly or CLM platform.

    How to select and implement the right tools

    Selecting the wrong tool is expensive, but the selection process itself does not need to be complicated. A few principles consistently separate successful implementations from failed ones.

    1. Start with high-volume, repeatable documents. The most effective automation strategy targets documents that consume the most administrative time first. Onboarding agreements, standard vendor contracts, and recurring invoices are better starting points than complex, one-off financial instruments.

    2. Require centralized template management. Without centralized governance, efficiency gains and compliance improvements are nullified even after tool adoption. Ask every vendor to demonstrate how template updates are controlled and distributed.

    3. Audit your integration requirements before signing. Map every system the new tool must connect to, including your ERP, CRM, and any banking or tax platforms. Tools with pre-built connectors to your existing stack reduce implementation risk substantially.

    4. Evaluate security certifications explicitly. For financial documents, SOC 2 Type II certification and data residency controls are non-negotiable requirements, not nice-to-haves.

    5. Budget for change management. The technology is rarely the hard part. Finance teams accustomed to manual processes need structured training and a clear explanation of how automation changes their daily work. Skipping this step is the most common reason automation projects underdeliver.

    Pro Tip: Run a 30-day pilot on a single document type before committing to a full deployment. The pilot will surface integration gaps and user adoption issues that no vendor demo will reveal.

    Key takeaways

    Financial document automation delivers measurable cost reduction, compliance control, and speed improvements when organizations match the right tool category to their specific document workflow problems.

    Point Details
    Match tool to document type Each category solves a specific problem; AP automation, CLM, and assembly tools are not interchangeable.
    Prioritize template governance Centralized template management is what separates real automation from digitized manual processes.
    Start with high-volume documents Automating repeatable document types first delivers faster ROI and smoother organizational adoption.
    Integration determines success A tool’s value depends on how cleanly it connects to your ERP, CRM, and finance systems.
    Compliance is a core benefit Enforced templates and audit trails reduce regulatory risk, not just processing time.

    Why I think most organizations are still buying the wrong tools

    I have watched finance teams spend six figures on CLM platforms when their actual bottleneck was invoice data extraction. The category confusion is real, and it costs organizations both money and momentum. The vendor landscape does not help. Most platforms market themselves as end-to-end solutions, which obscures the fact that they are genuinely excellent at one or two things and mediocre at everything else.

    The shift I find most significant right now is the move away from template-dependent extraction toward context-aware AI agents. Legacy OCR tools require someone to build and maintain a template for every document layout they encounter. When a supplier changes their invoice format, the template breaks and someone has to fix it manually. AI-powered tools like DocuPOW eliminate that dependency entirely by reading documents the way a trained analyst would, understanding what a field means rather than where it sits on the page. That is not a marginal improvement. It is a structural change in how financial document workflows operate.

    The organizations I see getting the most value from automation are not the ones with the biggest budgets. They are the ones that started with a clear problem statement, picked a tool that solved that specific problem well, and built governance around it before scaling. The technology is mature enough now that execution and governance are the real differentiators, not the software itself.

    — Sameer

    How DocuPOW fits your financial document workflow

    If your finance team is still manually keying data from invoices, contracts, or financial statements, DocuPOW’s intelligent document automation platform addresses that problem directly. Unlike template-based tools that break when document layouts change, DocuPOW uses autonomous AI agents to extract and structure data from any financial document format without manual configuration.

    https://docupow.ai

    The platform connects to existing ERP and finance systems, which means extracted data flows directly into your workflows without a separate integration project. For operations teams looking at the document process automation benefits in detail, DocuPOW’s real-time analytics layer also gives finance leaders visibility into processing volumes, error rates, and cycle times across every document type they handle.

    FAQ

    What are the main types of financial document automation tools?

    The main categories are OCR and AI-powered data extraction engines, accounts payable automation platforms, expense management tools, contract lifecycle management systems, document assembly tools, automated financial reporting software, and document management systems with built-in workflow automation. Each category addresses a distinct stage of the financial document lifecycle.

    How much can document automation reduce processing time?

    Document automation reduces drafting and processing time by 70% to 90%, with some organizations reporting contract processing times dropping from multiple days to under 20 minutes. ROI is typically realized within three to six months of deployment.

    What is the difference between a CLM platform and a document assembly tool?

    A CLM platform manages the full contract lifecycle from creation through renewal, including negotiation, obligation tracking, and compliance monitoring. A document assembly tool generates documents from templates by merging data but does not typically track post-execution obligations or manage contract renewals.

    How do I know which tool type my organization needs first?

    Identify the document type that consumes the most manual processing time in your finance team and start there. High-volume, repeatable documents like invoices and standard vendor contracts deliver the fastest ROI and the clearest proof of value before you expand automation to more complex document workflows.

    Do financial document automation tools require replacing existing ERP systems?

    No. The most effective financial automation tools are designed to integrate with existing ERP platforms like SAP, Oracle, and Microsoft Dynamics rather than replace them. The automation layer sits on top of your current systems and feeds structured data into them, which protects your existing technology investment.

  • Top 4 docupipe.ai Document Processing Alternatives 2026

    Top 4 docupipe.ai Document Processing Alternatives 2026

    Automating document data extraction often gets stuck on slow template setup, limited language support, or tools that do not scale for high-volume, audit-sensitive workflows. Many document processing software options still require manual mapping or lack critical compliance features like HIPAA or SOC 2, which keeps regulated organizations from a true hands-off system. This comparison details accuracy, integration, compliance, and setup speed across four top alternatives so you can match one to your workflow needs and data security standards without settling for a costly pilot.

    Table of Contents

    DocuPOW

    https://docupow.ai

    At a Glance

    ZeroShot learning lets DocuPOW extract data from new document types without prior training, cutting initial setup for novel formats to near zero. The platform pairs template-free, autonomous processing with API connectivity to push results directly into ERP and CRM systems.

    Core Features

    • ZeroShot learning for instant extraction from unfamiliar layouts.
    • Template-free autonomous processing across PDFs, PNGs, and JPEGs to avoid manual template builds.
    • API-driven integrations that validate, enrich, and route data into enterprise systems as part of automation workflows.
    • Real-time analytics and predictive insights for operational visibility.

    Key Differentiator

    DocuPOW’s single standout capability is ZeroShot learning, which removes the dependency on prebuilt templates. That means you can drop a new invoice or form type into the pipeline and extract structured fields immediately, rather than waiting for model retraining or rule authoring.

    Pros

    • Supports a wide variety of document types without templates, so projects that ingest diverse sources get faster time to usable data.
    • Continuous self-learning plus human feedback reduces manual correction over time, improving throughput and lowering headcount spent on validation.
    • Deep integration capabilities let you push cleansed data into ERP and CRM systems and feed dashboards with minimal glue code.
    • The platform includes real-time analytics and predictive insights that turn processed documents into operational signals for finance and supply chain teams.
    • The vendor advertises security measures including encryption and compliance with industry standards like HIPAA, which matters for regulated records.

    Cons

    • Implementation complexity can be significant in highly legacy or specialized enterprise environments; expect technical integration work and possible vendor support for advanced customizations.

    Notable Integrations

    DocuPOW connects to enterprise tech stacks commonly used in larger organizations:

    • ERP systems and CRM platforms for direct data flow.
    • Power BI and Power Automate for reporting and workflow orchestration.
    • Custom APIs for bespoke destinations and enrichment services.

    Who It’s For

    Large enterprises and organizations with high-volume, diverse document workflows that need automated, scalable extraction and direct routing into downstream systems. Particularly relevant to teams in finance, healthcare, and supply chain that require consistent structured output from mixed document estates.

    Unique Value Proposition

    ZeroShot learning plus template-free automation lets you add new document formats to production without pause. That reduces onboarding friction for global manufacturers and similar organizations, since new suppliers and country-specific forms no longer force weeks of template work before data becomes usable.

    Real World Use Case

    A global manufacturer replaced manual sorting of financial documents with DocuPOW, feeding extracted fields into its ERP for near real-time spend analytics. The change improved visibility into supplier spend and sped decision cycles for procurement and finance leaders.

    Pricing

    Pricing is variable and tied to volume and tier. The vendor states options that range from per-page pricing for mid-volume use to custom enterprise plans for high-volume deployments and bespoke integrations.

    Website: https://docupow.ai

    Docupath

    https://docupath.ai

    At a Glance

    Finance Finn, Legal Louise, and Customer Service Collin are productized AI assistants that target vertical workflows for finance, legal, and customer service teams.

    The platform emphasizes real-time validation and white-label partner deployment for embedded solutions.

    Core Features

    • AI-powered document understanding and data extraction for invoices, contracts, and customer paperwork.
    • Natural language commands that let operators instruct AI agents using plain English rather than building templates.
    • Real-time validation and fraud detection to catch mismatches before they enter downstream systems.
    • White-label capabilities and partner-friendly embedding for resellers and OEMs.

    Key Differentiator

    Docupath builds on an AI-native architecture with dynamic real-time routing and natural language instruction, which lets you shape extraction behavior on the fly rather than rebuilding templates.

    That design favors organizations that need adaptable parsing logic across many document types and languages.

    Pros

    • Vendor materials and review summaries praise its data extraction and OCR workflows for quick setup and time savings. That external praise shows it performs well in standard invoice and contract workstreams.

    • The natural language instruction model reduces engineering time for new document types; nontechnical operators can refine extraction rules without code.

    • Partner and white-label support makes Docupath practical for ISVs and resellers who need an embed-ready engine with rebranding options.

    • Flexible format and language support mean teams handling multilingual or mixed-format batches can keep a single processing pipeline.

    Cons

    • Public feedback outside prominent review platforms is limited, which makes independent validation harder when you evaluate alternatives.

    • The vendor places heavy reliance on AI accuracy; performance will vary with noisy, hand-written, or highly unconventional documents.

    • Documentation and case detail in public materials are light on edge-case failure modes and tuning effort required.

    When It May Not Fit

    If your procurement requires extensive third-party benchmarks or long-term independent audits, Docupath may feel underdocumented given the limited public feedback.

    Also avoid it when your document set includes extreme handwriting or ultra-custom forms that historically need bespoke extraction rules.

    Who It’s For

    Mid-sized to large organizations with high-volume document processing needs in finance, legal, or customer service who want partner-friendly deployment and vertical product packs.

    It suits teams willing to invest in AI tuning rather than lock into rigid template libraries.

    Real World Use Case

    A financial institution deploys Finance Finn to capture invoice fields, validate totals against purchase orders, and flag suspicious line items before posting.

    The result is fewer manual exceptions and faster throughput for the payment queue.

    Pricing

    The vendor does not publish standard pricing; pricing is informational only and typically set per engagement or partnership.

    Expect enterprise negotiation for volume, white-labeling, and SLAs rather than a fixed per-seat list price.

    Website: https://docupath.ai

    Eagle Doc

    https://eagle-doc.com

    At a Glance

    Eagle Doc’s marketing materials claim 95%+ accuracy and processing in under 5 seconds per page, a performance promise aimed at high-volume finance and accounting workflows. The vendor also advertises support for more than 40 languages and GDPR compliance with EU hosting.

    Core Features

    • Automated document data extraction from invoices, receipts, bank statements, IDs, and custom forms.
    • API and no-code dashboard for both developer integration and business-user configuration.
    • Supports 40+ languages, which helps multinational teams reduce manual translation work.
    • Specialized endpoints for invoices, receipts, signatures, and bank statements to speed parsing.
    • Fast throughput consistent with the speed figure above, which suits batch and near real-time use.

    Key Differentiator

    Eagle Doc emphasizes no templates or training required. The platform claims its models adapt automatically to any layout or language, so you do not map fields or supply sample batches before going live. That approach lowers initial setup time for teams replacing manual entry.

    Pros

    • Intuitive dashboard that nontechnical staff can use to monitor runs and correct extractions without calling developers.
    • The filing-style organization behaves like a virtual cabinet, making retrieval and audit trails straightforward for accounting teams.
    • Flexible pricing and a tangible free tier let you pilot with real documents before committing budget.
    • Broad document type coverage reduces the number of specialized tools needed for mixed workflows.
    • The speed figure above means processing can keep up with daily invoice volumes rather than forcing overnight batches.

    Cons

    • Some users report inconsistent or limited English support, which undermines confidence for English-first workflows.
    • Advanced configuration options are present but can confuse less technical operators, increasing support requests.
    • There are rare reports of files or extracted data not saving correctly, a risk for teams that need absolute audit reliability.

    When It May Not Fit

    If your operation requires granular, rule-based extraction maps or guaranteed per-document audit logs at the platform level, Eagle Doc’s automatic approach may feel restrictive. High-compliance teams needing airtight save guarantees or enterprise SLAs should plan for additional validation steps.

    Who It’s For

    Businesses and developer teams that need quick deployment for invoice, expense, and KYC processing across multiple languages. Best suited to mid-market finance, logistics, HR, and legal teams that value speed and minimal setup.

    Real World Use Case

    A medium-sized accounting firm uses Eagle Doc to ingest thousands of client invoices and receipts each month. Routine data entry drops dramatically, reconciliation finishes faster, and GDPR-aligned hosting eases client data concerns.

    Pricing

    Free tier available for up to 20 pages per month for initial testing. Paid plans start at €5 per month for 166 pages with the most popular at €59 per month for 1,966 pages. Custom enterprise plans and volume discounts are available.

    Website: https://eagle-doc.com

    Doctly.ai

    https://doctly.ai

    At a Glance

    Starts at $0.02 per page with a Professional tier at $499/month for up to 25,000 pages, plus a free trial with no credit card required. The vendor states SOC 2 and HIPAA compliance and reports adoption by Fortune 500 companies, claims the marketing materials emphasize rapid deployment without custom templates.

    Core Features

    • Supports PDFs, Word files, images, and scanned documents with multi-format ingestion.
    • AI extraction that recognizes tables, forms, handwriting, charts, and contextual fields.
    • Flexible export to JSON, CSV, Markdown, and XML for downstream systems.
    • Rapid API integration so teams can deploy without building custom templates or lengthy model training.
    • Continuous model updates applied without downtime according to the vendor.

    Key Differentiator

    The vendor positions Doctly.ai on combining high accuracy with enterprise security and fast time to value. That promise is aimed at compliance-sensitive operations that need production-ready extraction quickly rather than long pilot projects or custom model builds.

    Pros

    • High reported accuracy on complex layouts helps reduce manual validation in finance and legal workflows.
    • The vendor states SOC 2 and HIPAA compliance which supports regulated use cases and audit trails.
    • Rapid deployment via APIs removes the need for a dedicated ML team, letting IT connect extracts to databases and RPA tools quickly.
    • Flexible deployment choices include on-premises and private cloud, which suits organizations with strict data residency requirements.
    • Outputs in developer-friendly formats and webhook support make integrations with ERPs and case management systems straightforward.

    Cons

    • There is limited third-party review data available, so independent validation of long-term reliability is sparse.
    • Niche or highly specialized document types are not explicitly guaranteed to work without extra tuning or development work.
    • Buyers that require a heavily customized, no-code workflow orchestration layer may face additional integration effort.

    When It May Not Fit

    If your procurement team requires broad independent reviews or public case studies before purchase, the limited third-party feedback could slow approval. If you depend on unusually formatted proprietary documents, plan a pilot to verify extraction accuracy before full rollout.

    Who It’s For

    Large enterprises and compliance-sensitive organizations in finance, healthcare, insurance, and legal that need accurate, auditable extraction fast and that have engineering resources to integrate API outputs into existing systems.

    Real World Use Case

    The vendor describes a Fortune 500 financial client that automated extraction of complex financial tables and reports, which reduced manual effort and sped compliance checks. Use that example as a benchmark when sizing pilot scope and expected labor savings.

    Pricing

    Pricing begins at $0.02 per page on a pay-as-you-go basis. The Professional plan is $499/month for up to 25,000 pages. Custom enterprise packages are available for high-volume or tailored deployments, and a free trial is offered.

    Website: https://doctly.ai

    Comparative Analysis

    Evaluating the performance and offerings of document processing software involves analyzing their unique features, architectural approaches, and user value in diverse workflows.

    Performance Differences in Handling Document Variety

    DocuPOW integrates ZeroShot learning, effectively eliminating the need for prebuilt templates for recognizing and extracting data, which significantly accelerates the onboarding of novel document types. By contrast, Eagle Doc also employs adaptive technology requiring no templates; however, some users report discrepancies in supporting intricate English-based workflows. Docupath, on the other hand, features AI-led natural language instructions that simplify adapting parsers but still depend on user-provided instructions for tuning. For use cases demanding immediate, unconfigured adaptability to document formats, DocuPOW provides a streamlined option.

    Integration Depth and Security Provisions

    Implementing digital transformation efficiently requires integration capabilities and adherence to security standards. Doctly.ai offers SOC 2 and HIPAA compliance and features straightforward API integrations for processing sensitive data, advantageous for regulated industries. Meanwhile, DocuPOW advances ERP/CRM integration workflows by pushing pre-extracted data directly into operational systems, which reduces development overhead during deployment. However, Eagle Doc, despite offering GDPR-aligned European hosting, lacks an equivalent breadth of real-time data connectivity compared to its competitors, which limits its attractiveness for workflows needing dynamic data exchanges.

    Best Fit Recommendations

    • DocuPOW: Enterprises working with diverse document types and requiring autonomous systems for processing and integrating high-volume workflows into ERP/CRM systems would align best with this solution.
    • Eagle Doc: Multinational mid-market organizations prioritizing compliance and rapid implementation of multi-language invoice workflows should prefer this platform.
    • Doctly.ai: Compliance-centric operations needing secure extractions and diverse export options without lengthy deployment timelines may benefit significantly from this tool.

    Our Pick: DocuPOW

    DocuPOW demonstrates an advanced capability to handle various document formats immediately without configuration via its ZeroShot learning. This capacity streamlines workflows for large enterprises involving dynamic and heterogeneous document sets. While organizations requiring intensive audit tracking may consider alternatives like Doctly.ai, DocuPOW remains for reducing time-to-value in data processing automation.

    Document Processing Software Comparison

    Identify the ideal document processing platform for your organization’s needs by assessing these top alternatives based on their unique capabilities and integrations.

    Product Key Differentiator Best For Pricing Notable Limitation
    DocuPOW ZeroShot learning for non-template extraction Large enterprises with diverse workflows Not disclosed Integration complexity in legacy systems
    Docupath AI-native with natural language commands High-volume finance workflows Not disclosed Limited independent performance feedback
    Eagle Doc No templates necessary with fast throughput Multilingual processing teams Starts at €5/month for 166 pages Inconsistent English language support
    Doctly.ai Enterprise-grade extraction and SOC 2 compliance Compliance-sensitive large enterprises $0.02 per page or $499/month for 25,000 pages Sparse third-party validation

    Discover Why DocuPOW Stands Out Among docupipe.ai Alternatives

    Many organizations face the frustrating challenge of adapting to new document formats that slow down processing and increase manual work. The article highlights how docupipe.ai alternatives struggle with template dependency and complex setup. DocuPOW solves this by using ZeroShot learning and autonomous agents that extract data without templates or retraining. This means rapid onboarding for diverse documents, especially useful for global manufacturers aiming to improve financial visibility and speed decision-making.

    https://docupow.ai

    Experience the ease of automated document processing with DocuPOW. Visit DocuPOW now to explore how real-time analytics and API-driven workflows can reduce errors and transform your data handling. Import your first documents and see structured data ready for your ERP in minutes.

    Frequently Asked Questions

    How does DocuPOW’s ZeroShot learning enhance document processing efficiency?

    DocuPOW’s ZeroShot learning allows for instant extraction from new document types without prior training. This feature significantly reduces the initial setup time for novel formats, providing users with immediate access to usable data. Organizations can leverage this capability to streamline workflows without waiting for lengthy template creation.

    What is the difference between DocuPOW and Docupath in terms of user adaptability?

    Docupath excels in its use of natural language commands that enable nontechnical operators to refine extraction rules without coding. In contrast, DocuPOW provides a template-free solution focused on ZeroShot learning, making it ideal for diverse document formats without needing manual adjustments. Teams that prefer hands-on command flexibility might find Docupath better suited to their needs.

    Does Eagle Doc support multiple languages for international document processing?

    Eagle Doc supports over 40 languages, making it effective for multinational teams handling diverse document types. This wide support enables businesses to minimize manual translation work, ensuring smoother operations across various regions. Organizations requiring multilingual capabilities in their document workflows may find Eagle Doc to be a fitting option.

    Can I expect high accuracy from Doctly.ai in processing complex documents?

    Doctly.ai is reported to deliver high accuracy on complex layouts, which helps in reducing manual validation efforts for users. This capability makes it suitable for compliance-sensitive operations that require precise extraction quickly. However, it’s essential to pilot with your specific document types to ensure it meets your unique needs before full implementation.

    What document processing volume does DocuPOW accommodate effectively?

    DocuPOW can handle a high volume of diverse document workflows while providing immediate access to structured data. Its ZeroShot learning approach means users can introduce new formats to production without pausing operations, making it ideal for large enterprises with extensive document processing needs. Teams looking for a scalable and efficient solution will find DocuPOW advantageous.

  • How Document Automation Improves Throughput in 2026

    How Document Automation Improves Throughput in 2026

    Document automation is the process of using technology to automate the creation, population, routing, and storage of documents, eliminating manual, repetitive tasks and directly increasing how many documents your team can process per hour. For business professionals managing high-volume workflows, understanding how document automation improves throughput is no longer optional. It is the difference between a team that scales and one that drowns in paper. Platforms like DocuPOW, Formstack, and tools studied in Deloitte’s 2026 agreement management research all point to the same conclusion: automation compresses cycle times and multiplies output without adding headcount.

    How document automation improves throughput: the measurable gains

    Throughput, in document processing terms, means the number of completed documents your operation produces within a fixed time window. The most precise way to measure it is the documents per hour metric, which compares manual and automated processing against identical data sets. That single number cuts through ambiguity and gives decision-makers a defensible ROI figure before and after deployment.

    The gains documented across industries are not incremental. Financial institutions report a 100 to 130% increase in file throughput per staff member alongside a 67 to 70% reduction in cycle times. That means the same team processes more than twice the volume in less than a third of the original time. Mortgage file processing, for example, dropped from 8 to 15 days down to 2 to 3 days. KYC and CDD workflows fell from 5 days to under 24 hours.

    How to Create a Document Management Workflow - KDAN Blog

    Legal document automation tells a similar story. Automating contract assembly reduces drafting time from 2.5 hours to roughly 14 minutes, a 91% reduction. Error rates dropped from 4.3% to 0.4% in the same workflows. Fewer errors mean fewer rework loops, and rework loops are one of the most underestimated throughput killers in any document-heavy operation.

    Workflow type Throughput gain Cycle-time reduction
    Mortgage file processing 100 to 130% more files per staff member 8 to 15 days reduced to 2 to 3 days
    KYC/CDD compliance Significant volume increase per analyst 5 days reduced to under 24 hours
    Contract drafting 91% time reduction per document 2.5 hours reduced to 14 minutes
    High-volume record generation 20,000+ records per run Delays reduced by up to 85%

    Pro Tip: Measure throughput separately for document generation and for downstream tasks like approvals or storage. Conflating the two makes it easy to mistake a partial automation win for a full workflow gain, and you will miss the real bottleneck.

    Which workflow steps benefit most from automation?

    Not every step in a document workflow responds equally to automation. The biggest throughput gains concentrate in five specific phases, and knowing which ones to target first saves months of implementation time.

    • Data classification and extraction. AI-powered extraction pulls structured and unstructured data from source documents without manual keying. This eliminates the single most time-consuming step in most intake workflows and directly cuts the time-to-first-draft.

    • Document assembly and population. Template-driven assembly with live data feeds replaces manual drafting. The 91% drafting time reduction cited in legal automation comes almost entirely from this step. When a system auto-populates a 40-field contract in seconds, the throughput impact is immediate.

    • Validation and exception handling. AI validation catches formatting errors, missing fields, and data mismatches before a document moves forward. Fewer exceptions mean fewer manual review cycles, which is where most cycle-time inflation actually lives.

    • Routing and approvals. Approval bottlenecks are a throughput constraint that pure document speed cannot fix. Automated routing sends documents to the right reviewer the moment they are ready, with no handoff delays. The Deloitte and Docusign 2026 study found that linking data and automating routing reduces handoffs and measurably improves speed in approval-heavy workflows.

    • Storage and indexing. Automated filing with metadata tagging eliminates the post-processing queue that often adds hours to a document’s total cycle time.

    The document automation impact on productivity is highest when all five phases connect into a single end-to-end workflow rather than isolated point solutions. A system that automates extraction but leaves routing manual will still hit a wall at the approval stage.

    Pro Tip: When mapping your current workflow, time each phase separately. You will almost always find that 70 to 80% of total cycle time sits in two or three steps, not spread evenly. Automate those first.

    Infographic of document automation workflow steps

    How platform architecture shapes throughput at scale

    The intelligence inside a document automation platform matters. But the execution architecture underneath it matters just as much, and most buyers overlook it entirely.

    Batch processing and high-volume generation modes determine how a platform behaves under load. Formstack’s High-Volume Generation mode processes over 20,000 records per run with adjustable batch sizes ranging from 1 to 200 records, reducing delays by up to 85% compared to standard batch processing. That kind of scalability does not come from smarter document intelligence. It comes from how the platform manages memory, concurrency, and recovery when a run fails mid-stream.

    Architecture factor Lower-capability platforms Higher-capability platforms
    Batch size control Fixed, often small Configurable, up to 200+ records
    Parallel processing Sequential only Concurrent runs across queues
    Failure recovery Manual restart required Automatic recovery mid-run
    Peak volume handling Degrades under load Maintains throughput at scale

    Parallel processing is the most direct throughput multiplier at the platform level. When a system can run multiple document generation queues simultaneously, total output scales with workload rather than being capped by a single processing thread. This is how organizations handle end-of-month reporting spikes or regulatory filing deadlines without adding staff or extending hours.

    Batch sizing and parallelism also affect memory stability during very large runs. A platform that crashes at 5,000 records and requires a manual restart does not just lose time on the restart. It breaks the throughput measurement entirely and introduces unpredictable delays into downstream workflows. Choosing a platform with automatic recovery and configurable concurrency is a technical decision with direct operational consequences.

    What steps maximize throughput gains from document automation?

    Implementation quality determines whether an organization captures the gains the research promises or settles for a fraction of them. These steps reflect what consistently separates high-performing deployments from stalled ones.

    1. Start with high-volume, repeatable workflows. Automation performs best on structured, rule-based tasks with predictable inputs. Accounts payable invoice processing, onboarding document packages, and compliance reporting are ideal starting points. They generate immediate, measurable throughput data and build organizational confidence.

    2. Establish a baseline before you automate anything. Record your current documents-per-hour rate, average cycle time, and error rate for the target workflow. Without a baseline, you cannot validate gains, and you cannot identify which step is still limiting throughput after automation goes live.

    3. Segment your workload by exception rate. High-exception workflows require more human judgment and will always cap your throughput gains. Separate clean, structured documents from messy, variable ones and automate the clean segment first. This approach, supported by Shopify’s analysis of AI efficiency, limits human intervention to genuine judgment calls rather than routine processing.

    4. Automate routing alongside document generation. Teams that automate document creation but leave approval routing manual consistently underperform on cycle-time metrics. The Deloitte 2026 findings show 36% efficiency gains in time savings when AI covers the full agreement lifecycle, not just drafting. Legal teams reclaimed 37% of their time; HR teams reclaimed 45%.

    5. Use no-code or low-code platforms for faster iteration. Platforms that allow non-technical staff to modify templates and routing rules reduce the change management burden significantly. When a business rule changes, a no-code platform lets an operations manager update the workflow in hours rather than waiting weeks for an IT ticket.

    6. Run a pilot, measure it rigorously, then scale. A pilot on one workflow with clean measurement gives you the throughput data to justify broader rollout. It also surfaces the exception types and edge cases that would otherwise derail a larger deployment.

    Key takeaways

    Document automation improves throughput by compressing cycle times, eliminating rework loops, and enabling parallel processing at scale, with documented gains of 100 to 130% in file throughput and 67 to 70% in cycle-time reduction across financial and legal workflows.

    Point Details
    Measure throughput precisely Use documents per hour before and after automation to generate defensible ROI data.
    Target assembly and routing first Contract drafting and approval routing deliver the largest cycle-time reductions per automation dollar.
    Platform architecture matters Configurable batch sizes, parallel processing, and automatic recovery determine throughput at scale.
    Start with repeatable workflows High-volume, rule-based processes minimize exceptions and maximize early throughput gains.
    Automate the full lifecycle Covering extraction, assembly, routing, and storage together captures the full efficiency gain.

    Why throughput deserves to be your primary automation metric

    I have watched organizations invest in document automation and then measure success by cost savings alone. They get a number they can present to finance, declare victory, and move on. Six months later, the operations team is still complaining about turnaround times, and nobody can explain why.

    The problem is that cost savings are a lagging indicator. Throughput is a leading one. When you track documents per hour and cycle time, you see the bottleneck in real time. You know immediately whether the automation is working or whether a manual approval step is eating the gains you just engineered into the generation phase.

    The Deloitte 2026 research makes this explicit. Efficiency gains from automation come primarily from cycle-time reduction and fewer exceptions requiring manual review, not from labor cost reduction. That is a meaningful distinction. It means the path to better throughput runs through accuracy and routing clarity, not just faster typing.

    What I find most organizations miss is the approval layer. They automate document creation beautifully and then send the finished document into a queue where it waits three days for a signature. The document automation impact on productivity is real, but it stops at the handoff. If you are not measuring end-to-end cycle time from intake to final storage, you are measuring the wrong thing.

    My honest recommendation: run a 30-day pilot on one high-volume workflow, measure every phase separately, and present the throughput data to leadership before you ask for budget to scale. The numbers speak for themselves when you measure them correctly.

    — Sameer

    See how DocuPOW accelerates document throughput

    https://docupow.ai

    DocuPOW’s AI-powered platform is built specifically for organizations that need to process high document volumes without adding headcount. Its autonomous agents extract data from unstructured files without rigid templates, feed that data directly into document assembly, and route completed documents through configurable approval workflows. For manufacturers, real estate operations, and financial teams, this means the kind of throughput gains in operations that show up in your cycle-time reports within weeks of deployment. Explore DocuPOW’s high-volume processing guide to see the architecture behind the results, or visit DocuPOW’s automation platform to match the right solution to your workflow.

    FAQ

    What does document automation throughput actually measure?

    Throughput in document automation measures the number of completed documents processed within a fixed time period, typically expressed as documents per hour. Comparing this metric before and after automation gives you a direct, defensible measure of productivity gain.

    How much throughput improvement can a business realistically expect?

    Financial institutions have documented 100 to 130% throughput increases per staff member alongside 67 to 70% cycle-time reductions after deploying document automation. Results vary by workflow complexity and exception rate, but double-digit gains are consistent across industries.

    Which document workflows see the fastest throughput gains?

    High-volume, rule-based workflows with structured inputs, such as contract generation, mortgage processing, and compliance reporting, respond fastest to automation. These workflows have predictable data patterns that minimize exceptions and allow automation to run without frequent human intervention.

    Does platform architecture affect throughput as much as AI capability?

    Yes. Batch sizing, parallel processing, and automatic failure recovery can influence throughput independently of how intelligent the document extraction is. Formstack’s configurable batch architecture, for example, reduces processing delays by up to 85% compared to standard batch modes on the same data.

    What is the biggest mistake organizations make when automating for throughput?

    The most common mistake is automating document generation while leaving approval routing manual. This creates a new bottleneck at the handoff stage that cancels out the cycle-time gains from faster document creation. Automating the full lifecycle, from extraction through routing to storage, is what delivers the throughput improvements the research documents.